Abstract
Referring Multi-Object Tracking in satellite videos (RMOT-SV) aims to track multiple targets in remote sensing imagery using natural language descriptions. Existing benchmarks remain limited in scale and annotation diversity, with short and simple expressions that provide insufficient support for complex scenarios involving multiple tiny objects. To address these limitations, we present SatRMOT, the largest and most diverse benchmark for referring multi-object tracking in satellite videos. SatRMOT is characterized by three key properties: (i) larger scale, with 523 videos, 138k frames, and 19k referring expressions, substantially exceeding existing RMOT-SV benchmarks; (ii) richer expressions, where each video is annotated with diverse natural language descriptions involving motion patterns, spatial relations, and contextual cues; and (iii) multi-object referring for tiny targets, where expressions frequently describe multiple small objects, particularly cars, in dense and complex satellite scenes. A multi-agent collaborative framework is developed to enable scalable and high-quality annotation with reduced human labor and time costs. Building upon this dataset, we propose Dual Refinement Track (DRTrack), a strong baseline for RMOT-SV that performs joint visual-linguistic refinement. Extensive experiments demonstrate the challenging nature of our dataset and the effectiveness of our method.
Data Sources
SatRMOT reannotates and extends public satellite MOT datasets, including SatVideoDT, SatMTB-MOT, AIR-MOT, and VISO. The original image sequences were captured by Jilin-1 03 satellites across diverse regions worldwide, including China, the USA, Mexico, France, Italy, Spain, Australia, Japan, Turkey, India, Thailand, Saudi Arabia, and the United Arab Emirates (UAE), between 2017 and 2021. All sequences are represented in true color using spectral channels B1 (580-723 nm), B2 (489-585 nm), and B3 (437-512 nm), with a spatial resolution of 0.92 m at the sub-satellite point. Each video covers an area of approximately 11 km × 4.6 km and is recorded at 10 FPS.
Category-wise Video Examples
Category-wise Image Examples
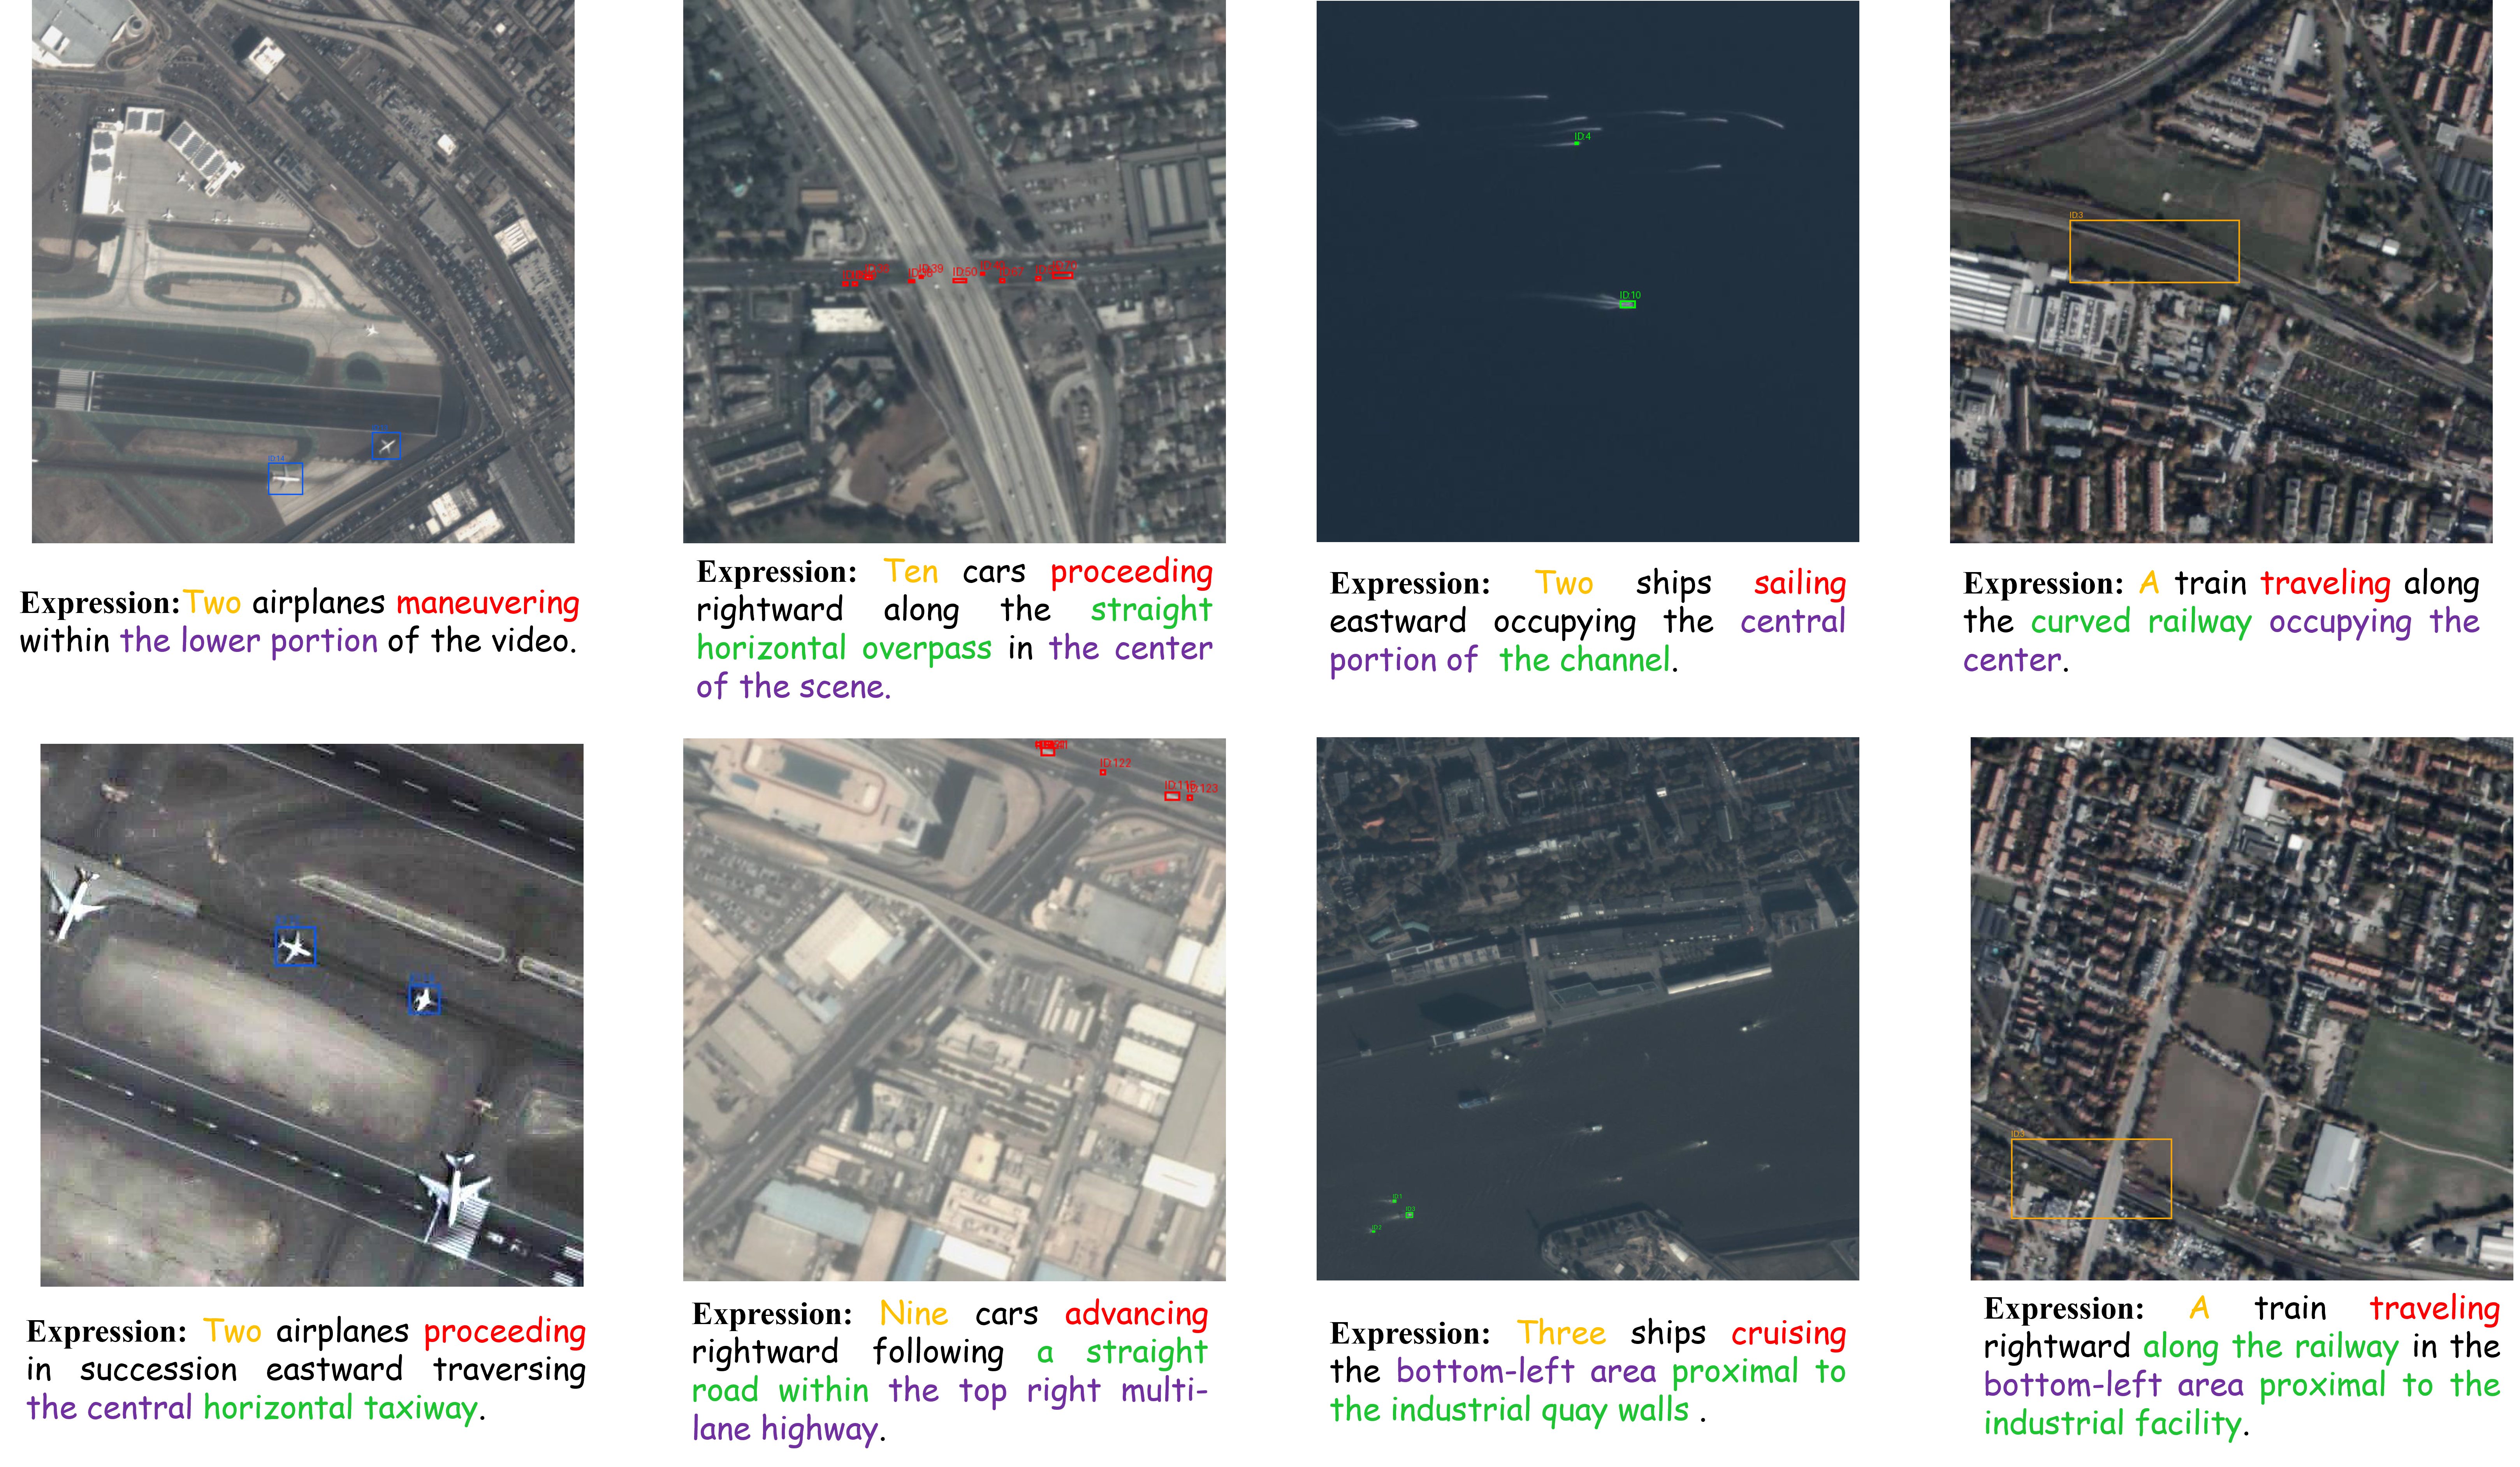
Figure 1. Category-wise image examples from SatRMOT. Each sample is annotated with a referring expression describing multiple targets using rich semantic cues, including object category, quantity, motion, spatial location, and structural context.
Expression Diversity Matters
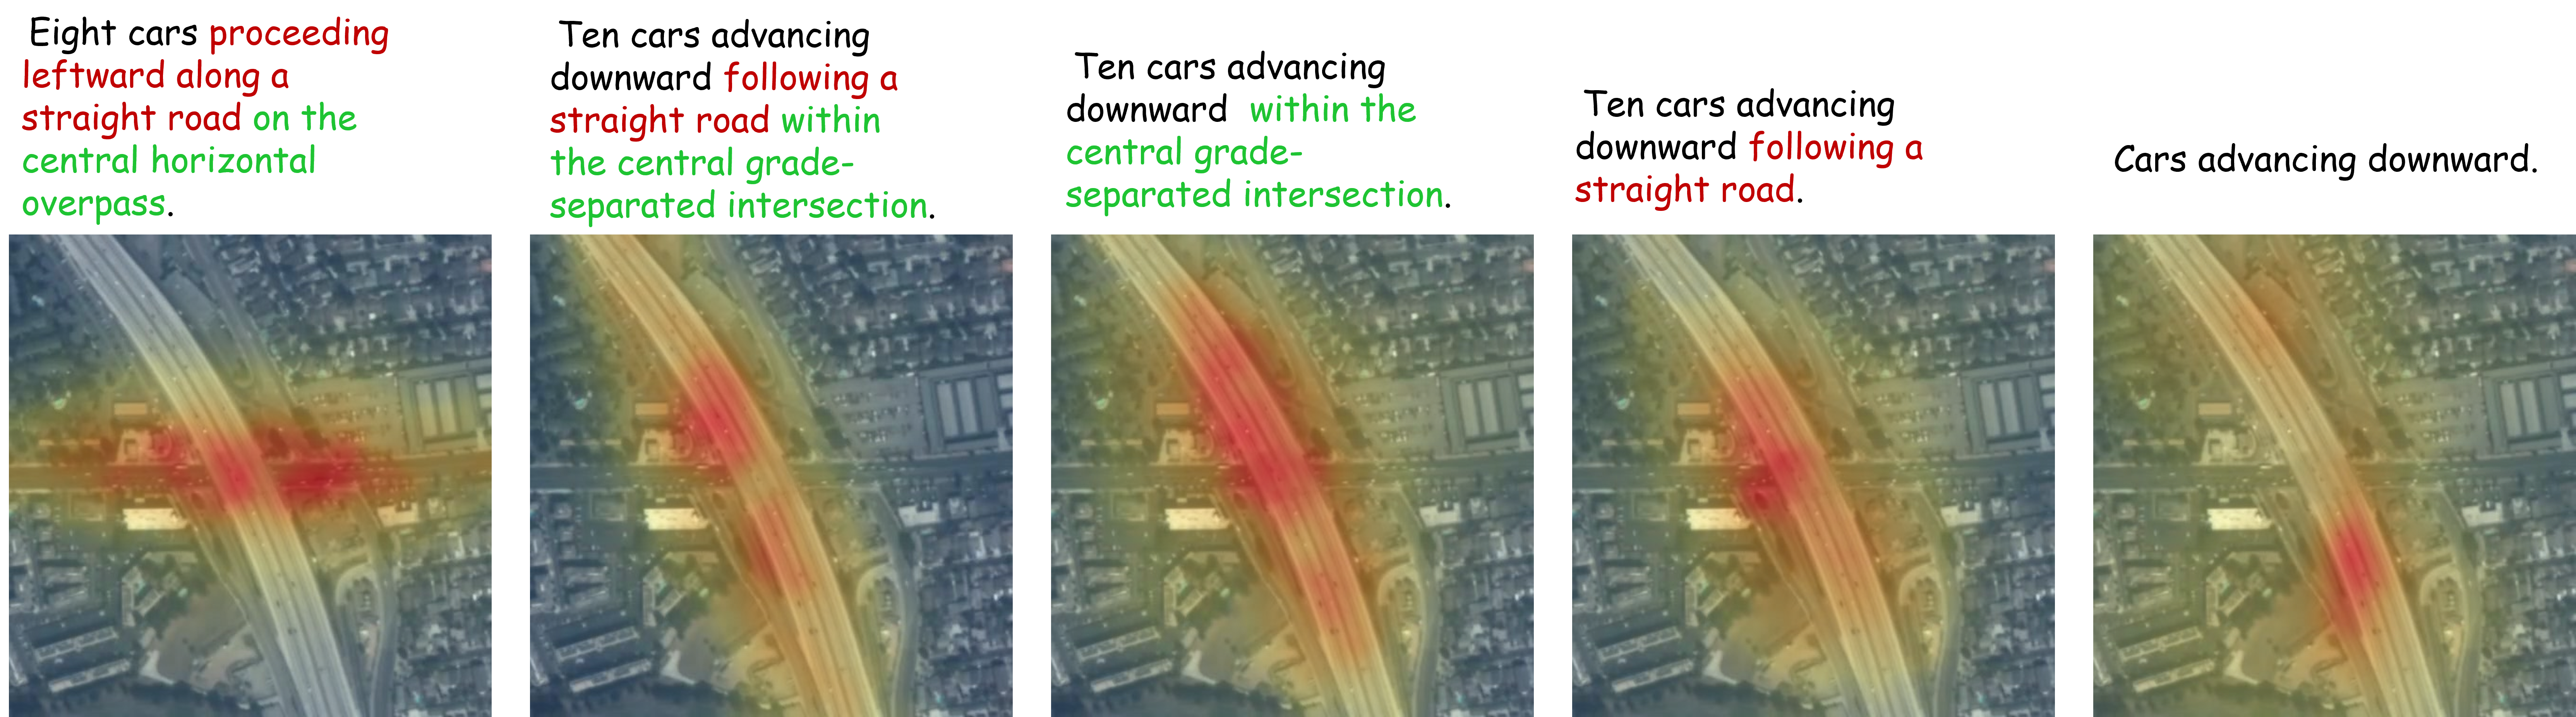
Figure 2. DRTrack responses to the same satellite image under referring expressions with different attributes. The response maps shift toward different visual regions as the language changes, showing why SatRMOT emphasizes diverse annotations that cover category, quantity, motion, direction, and spatial cues rather than a single coarse description.
Dataset Statistics
Global Statistics Overview
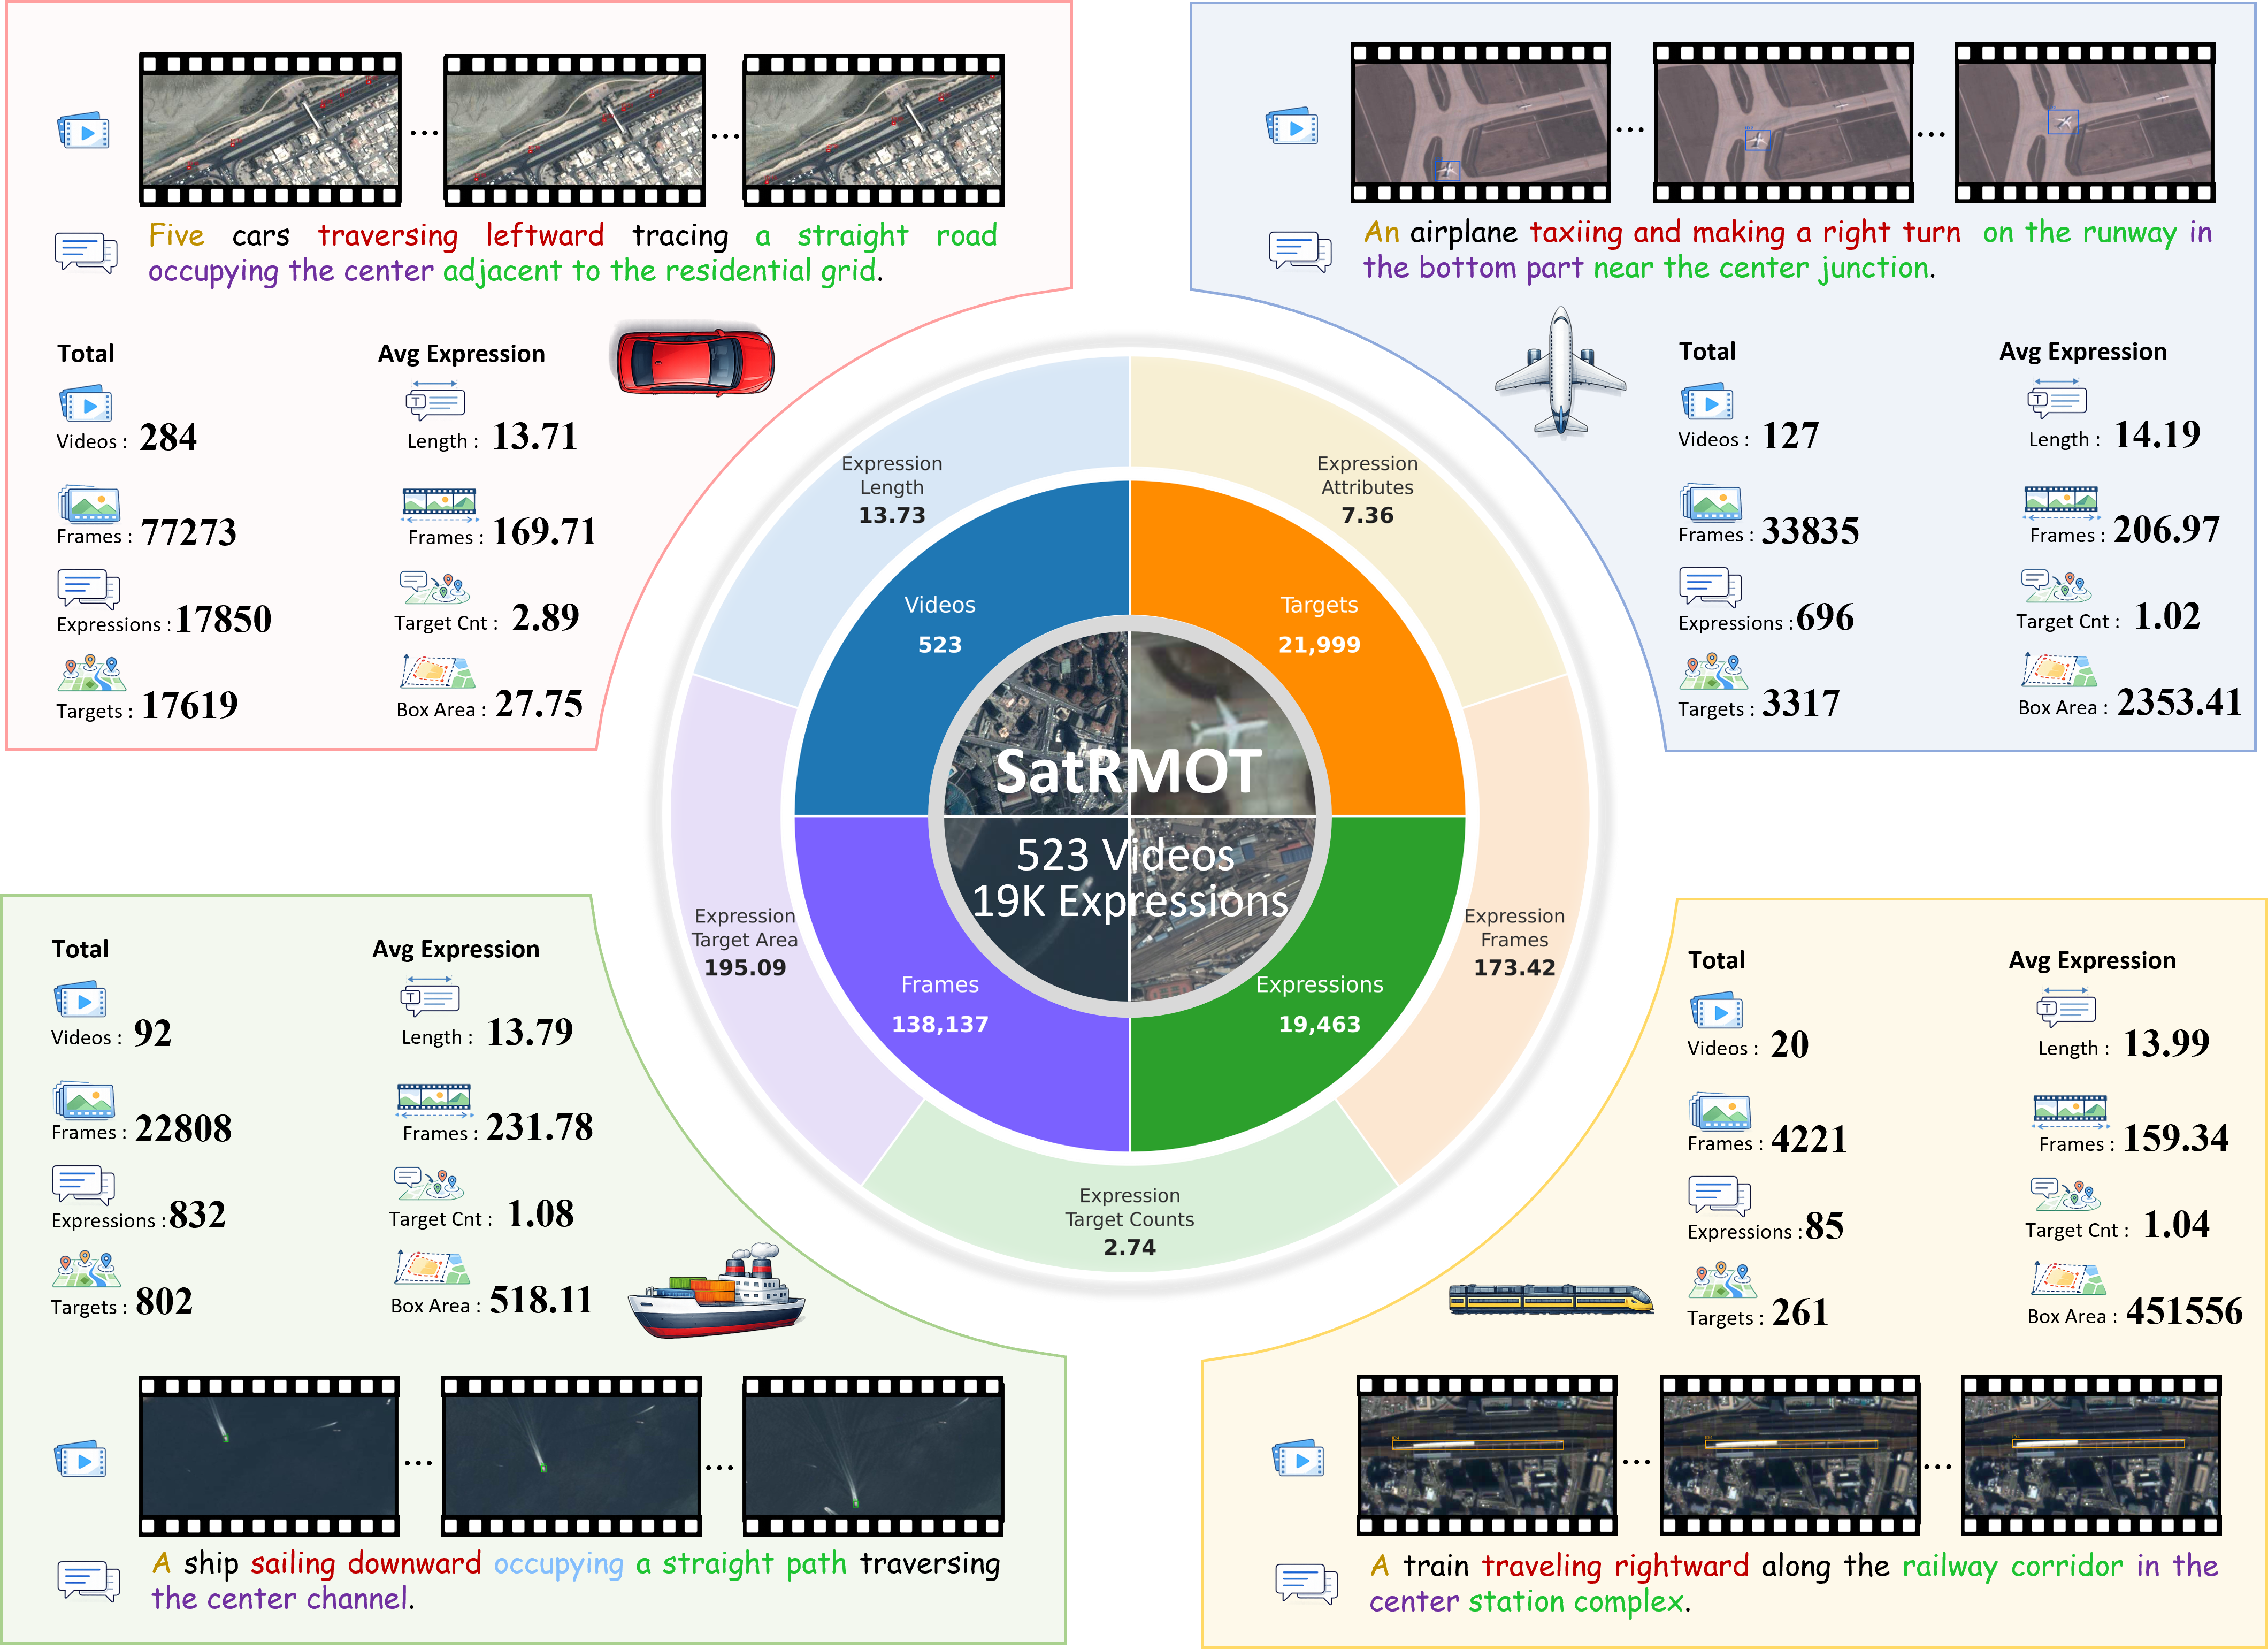
Figure 3. The overview of dataset statistics for SatRMOT. The central rings summarize global statistics across all videos, while the surrounding panels present category-wise distributions. These statistics highlight the large-scale nature of the dataset, as well as its rich expression complexity and diverse target characteristics across different object categories.
Dataset Comparison and Additional Analysis
| Dataset | Total expressions | Vocabulary | Total frames | Total videos | Expression length | Category | Targets |
|---|---|---|---|---|---|---|---|
| Refer-KITTI | 818 | 49 | 6650 | 18 | 4.62 | 2 | 785 |
| Refer-KITTIv2 | 9800 | 617 | 7162 | 21 | 6.54 | 2 | 932 |
| Refer-Dance | 1900 | 25 | 67300 | 65 | 7.6 | 1 | 692 |
| RefSat | 556 | 80 | 31130 | 212 | 6.15 | 4 | 4588 |
| SatRMOT (ours) | 19463 | 1313 | 138137 | 523 | 13.73 | 4 | 21999 |
Table 1. Comparison with existing referring tracking datasets. SatRMOT contains substantially more expressions, a richer vocabulary, more videos and frames, and many more annotated targets than previous benchmarks.
Table 2. Expressions by Category
| RMOT-SV Dataset |
Car | Airplane | Ship | Train |
|---|---|---|---|---|
| RefSat | 5 | 309 | 178 | 49 |
| SatRMOT | 17850 | 696 | 832 | 85 |
Table 3. Expression Attributes
| RMOT-SV Dataset |
Target Quantity |
Motion Direction |
Motion Status |
Spatial Location |
Structural Context |
|---|---|---|---|---|---|
| RefSat | × | × | ✓ | × | × |
| SatRMOT | ✓ | ✓ | ✓ | ✓ | ✓ |
Category-level expression counts and supported semantic attributes are summarized for RMOT-SV benchmarks.
Figure 4. Rich semantic coverage in SatRMOT expressions, including target cardinality, motion patterns, spatial relations, direction cues, and diverse scene context.
Multi-Agent Rich Referring Annotations
Overview
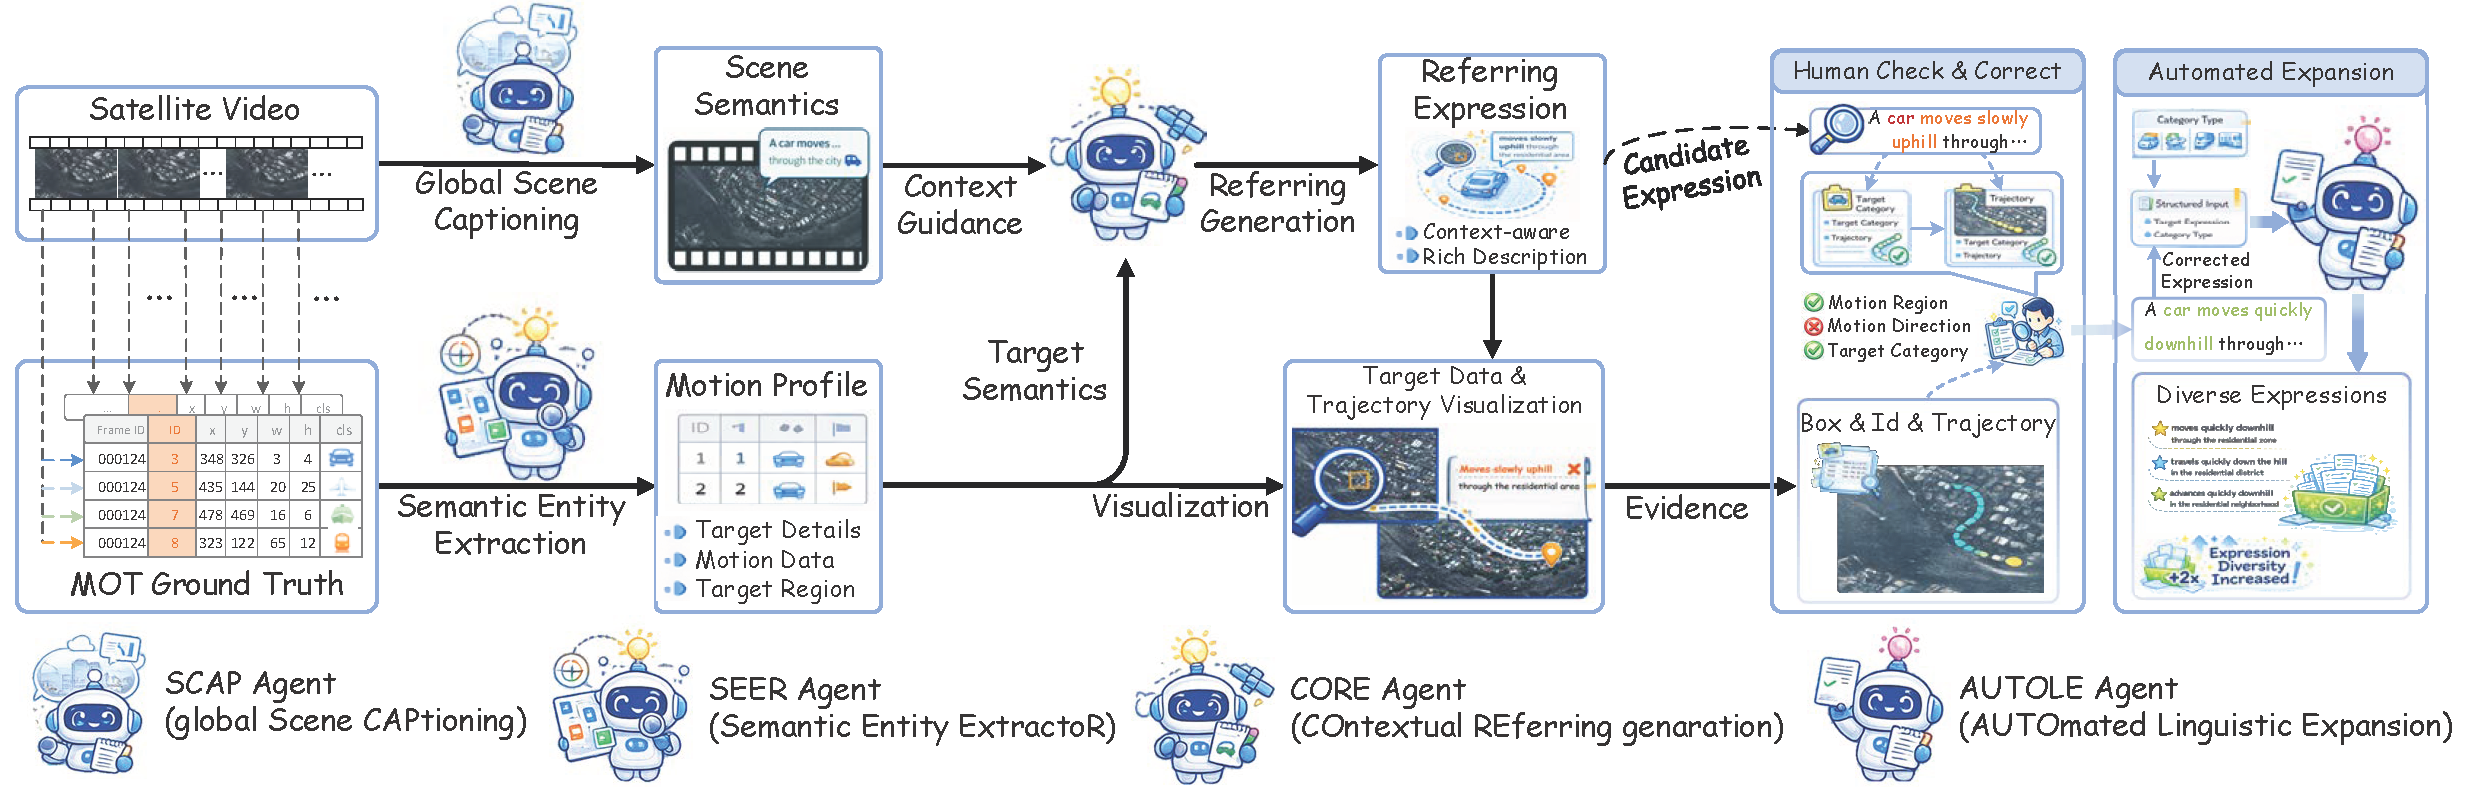
Figure 5. The overview of the proposed semi-automatic multi-agent framework for generating rich referring expressions in satellite videos. The pipeline coordinates multiple agents, including SCAP for global scene captioning, SEER for semantic entity extraction, CORE for context-aware referring expression generation, and AUTOLE for automated linguistic expansion, together with human-in-the-loop verification to ensure semantic correctness and annotation quality.
Human-in-the-Loop Correction
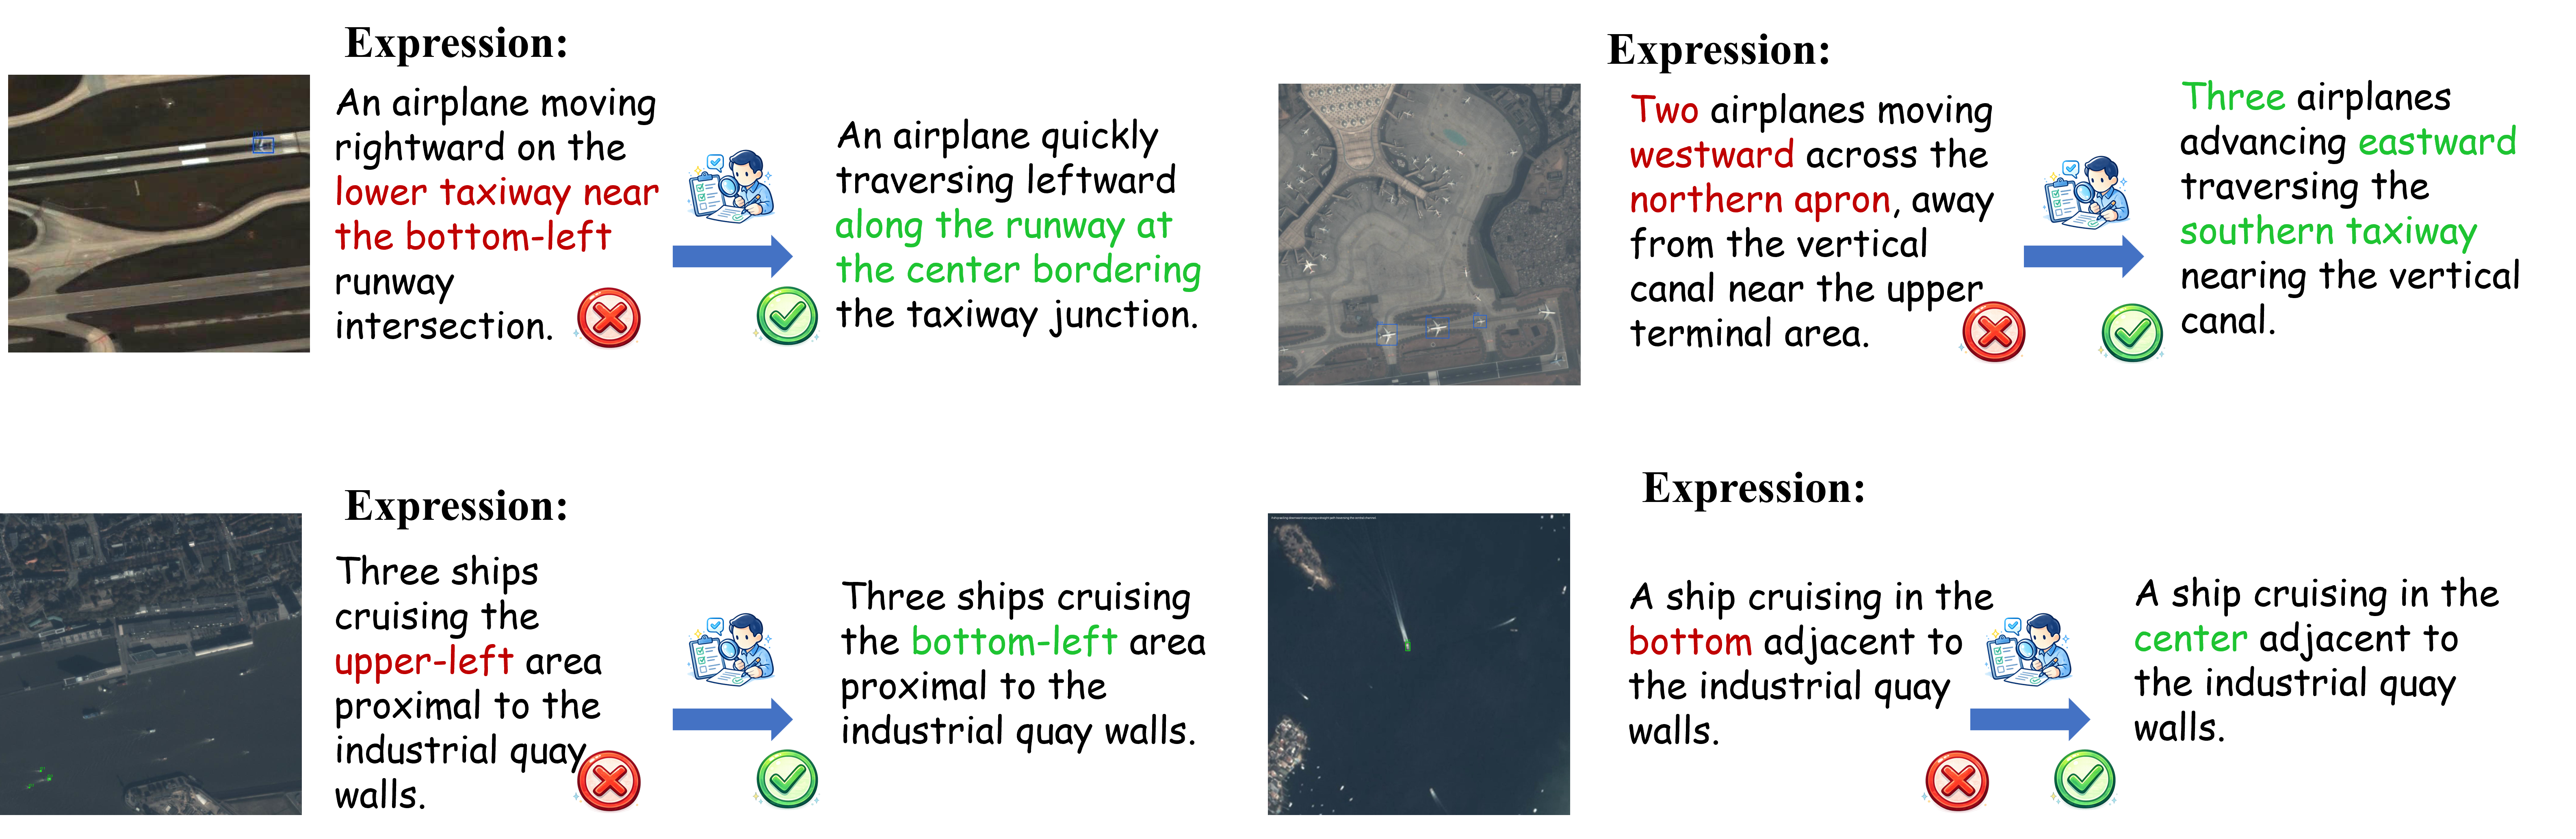
Figure 6. Failure cases produced by the annotation assistant and corrected through human-in-the-loop verification. Human review fixes inaccurate target grounding and expression mismatches, preserving the scalability of the multi-agent pipeline while keeping the final referring annotations reliable.
SCAP Agent
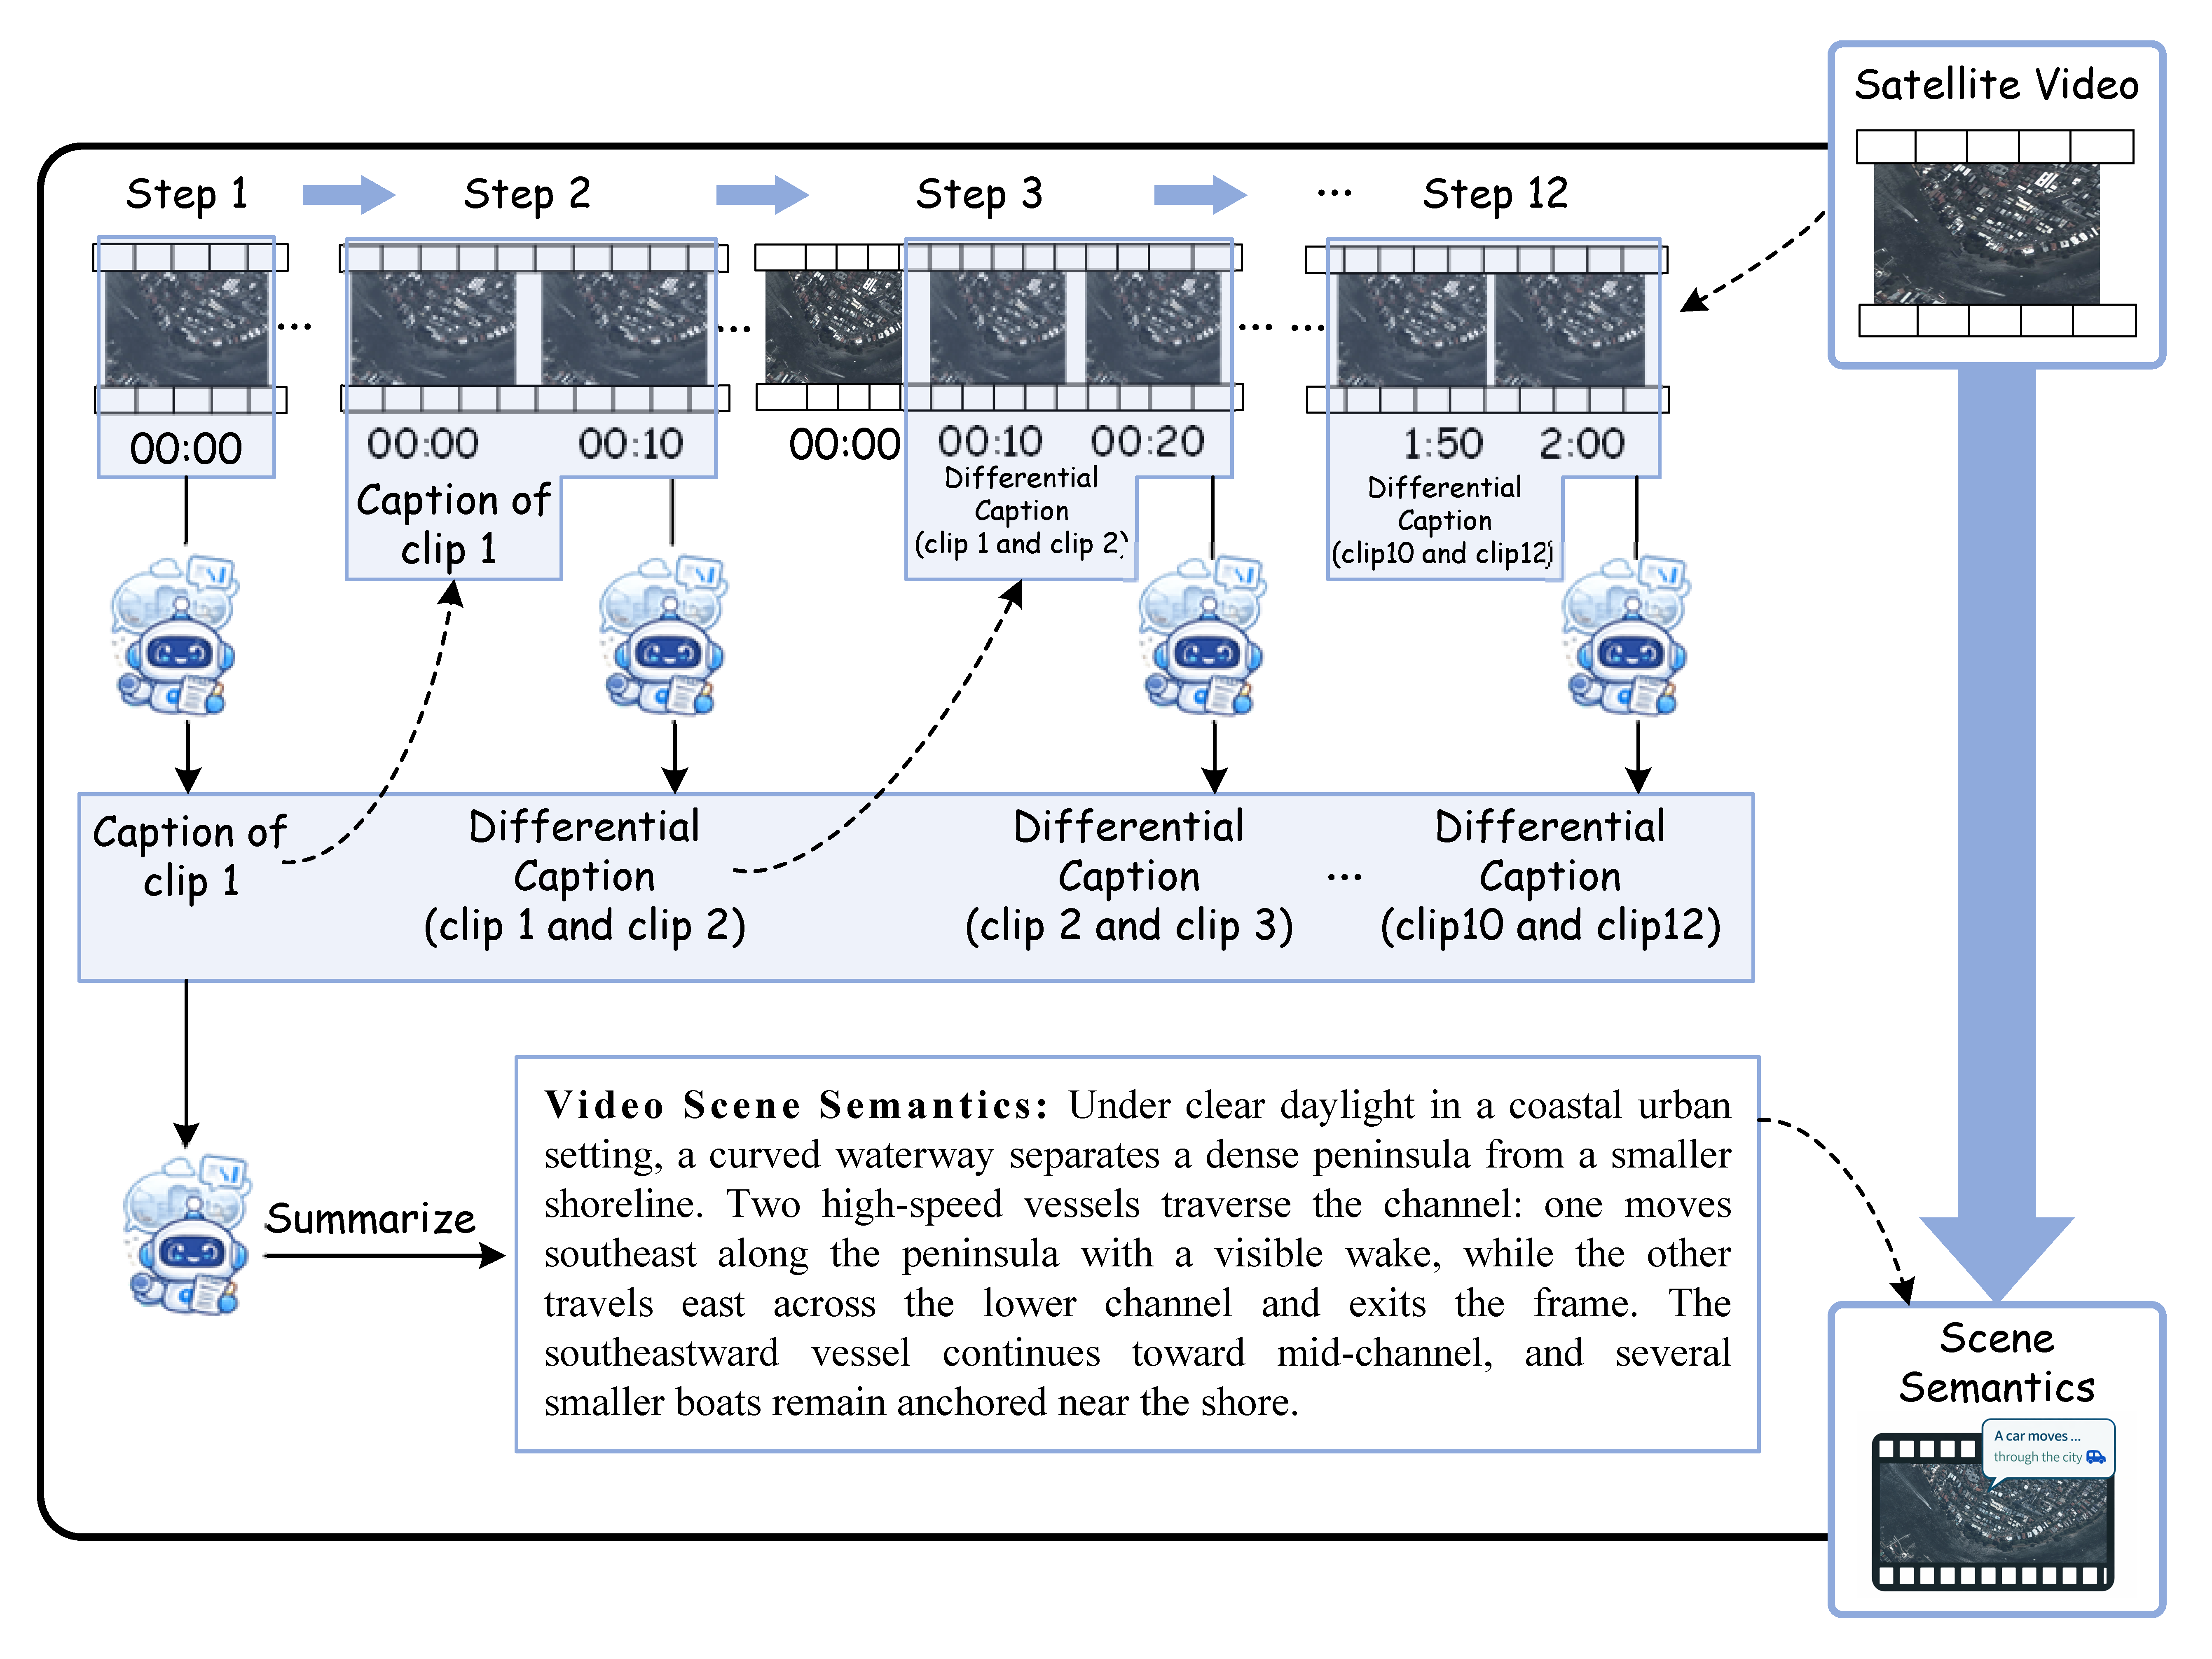
Figure 7. SCAP agent workflow for constructing temporally coherent scene captions from satellite video clips.
I am the SCAP agent, and my workflow is illustrated in Figure 7 on the left. I process a satellite video by first splitting it into a sequence of temporal clips. For the opening clip, I generate an initial caption to capture the overall scene layout and target distribution. I then compare consecutive clips and produce differential descriptions that reflect how objects move and evolve over time. By progressively accumulating these intermediate observations, I finally build a coherent scene-level summary that provides a concise and temporally consistent understanding of the full video.
SEER Agent
Figure 8. SEER agent workflow for extracting motion semantics, grouping targets, and estimating motion regions from MOT annotations.
I am the SEER agent, and my workflow is illustrated in Figure 8 above. Starting from MOT annotations such as object IDs, bounding boxes, and category labels, I parse them into structured motion semantics. In this process, I iteratively call four specialized tools: Kalman Filtering to smooth trajectories, Direction-Angle Computation to infer motion direction and turning behavior, DBSCAN Clustering to group targets with similar dynamics, and Motion-Region Estimation to determine where each target moves within the scene. From these analyses, I construct motion profiles that describe each target in terms of its motion pattern, direction, speed, and region. Whenever multiple targets exhibit consistent motion behaviors, I automatically associate them into unified groups, enabling coherent multi-object descriptions grounded in their trajectories.
CORE Agent
I am the CORE agent. My role is to turn structured target attributes and global scene context into concise referring expressions. For each target, I combine its category, spatial region, motion pattern, and quantity with the overall scene description, then write a precise natural language query tailored for referring multi-object tracking. Controlled generation helps me keep every expression accurate, compact, and consistent with the surrounding context. In this way, I produce semantically grounded descriptions that bridge low-level motion cues and high-level language understanding.
AUTOLE Agent
I am the AutoLE agent. My role is to refine existing referring expressions by generating multiple linguistically diverse variants while preserving their original structure and meaning. For each input expression, I produce alternative phrasings that broaden the language space while keeping key cues such as motion, region, and object identity intact. In this way, I enrich the supervision signals used for referring multi-object tracking without changing the underlying semantics of the original descriptions.
Efficiency Advantages
Method Overview
Figure 9. The overview of DRTrack, a dual-refinement framework that enhances both visual and linguistic representations for referring multi-object tracking. It incorporates a Scale-aware Visual Refinement (SVR) module for multi-scale visual enhancement and a Linguistic-Conditioned Refinement (LCR) Decoder for language-guided query refinement, enabling accurate grounding and robust tracking in complex satellite scenes.
Experiments
Comparison with Existing Methods
| Cat | Method | HOTA | DetA | AssA |
|---|---|---|---|---|
| Car | iKUN | 12.11 | 4.74 | 31.07 |
| TransRMOT | 12.18 | 4.78 | 31.04 | |
| TempRMOT | 12.03 | 4.51 | 32.12 | |
| DKGTrack | 12.15 | 5.66 | 26.15 | |
| DRTrack | 13.77 | 7.62 | 24.92 |
| Cat | Method | HOTA | DetA | AssA |
|---|---|---|---|---|
| Airplane | iKUN | 41.80 | 31.97 | 54.68 |
| TransRMOT | 45.08 | 38.66 | 52.57 | |
| TempRMOT | 43.67 | 34.30 | 55.64 | |
| DKGTrack | 48.21 | 41.16 | 56.47 | |
| DRTrack | 48.69 | 40.27 | 58.88 |
| Cat | Method | HOTA | DetA | AssA |
|---|---|---|---|---|
| Ship | iKUN | 25.02 | 16.09 | 38.94 |
| TransRMOT | 25.23 | 16.57 | 38.44 | |
| TempRMOT | 25.98 | 17.19 | 39.30 | |
| DKGTrack | 25.50 | 17.43 | 37.37 | |
| DRTrack | 26.44 | 18.59 | 37.68 |
| Cat | Method | HOTA | DetA | AssA |
|---|---|---|---|---|
| Train | iKUN | 0.73 | 0.03 | 20.15 |
| TransRMOT | 0.54 | 0.01 | 20.94 | |
| TempRMOT | 0.58 | 0.02 | 21.26 | |
| DKGTrack | 0.63 | 0.02 | 20.30 | |
| DRTrack | 0.55 | 0.01 | 30.67 |
Table 4. Category-wise comparison with existing methods on SatRMOT. The four category-specific result blocks are grouped as one table, covering Car, Airplane, Ship, and Train with HOTA, DetA, and AssA.
Cross-Dataset Comparison
We further evaluate DRTrack on two existing referring tracking datasets, RefSat and RefKITTI, to examine its performance beyond SatRMOT. These results report the standard HOTA-family metrics and provide a direct comparison with representative RMOT methods under different data distributions.
Table 5. RefSat Benchmark
| Dataset | Method | HOTA | DetA | AssA | DetRe | DetPr | AssRe | AssPr | LocA |
|---|---|---|---|---|---|---|---|---|---|
| RefSat | iKUN | 16.98 | 5.93 | 50.90 | 10.67 | 11.33 | 53.52 | 82.36 | 73.19 |
| TransRMOT | 23.84 | 10.13 | 57.93 | 20.97 | 15.78 | 61.80 | 83.99 | 77.11 | |
| TempRMOT | 24.77 | 11.42 | 55.69 | 22.55 | 17.90 | 59.81 | 81.90 | 76.06 | |
| RSRefTrack | 32.77 | 17.82 | 62.88 | 26.91 | 31.15 | 67.03 | 84.27 | 77.20 | |
| DRTrack | 33.21 | 18.12 | 60.98 | 26.42 | 36.41 | 76.98 | 76.58 | 84.35 |
Table 6. RefKITTI Benchmark
| Dataset | Method | HOTA | DetA | AssA | DetRe | DetPr | AssRe | AssPr | LocA |
|---|---|---|---|---|---|---|---|---|---|
| RefKITTI | iKUN | 48.84 | 35.74 | 66.80 | 51.97 | 52.25 | 72.95 | 87.09 | - |
| TransRMOT | 45.65 | 36.15 | 57.86 | 54.58 | 50.65 | 61.15 | 89.96 | 90.33 | |
| TempRMOT | 50.31 | 38.48 | 65.93 | 52.23 | 57.88 | 70.98 | 87.76 | 90.40 | |
| DKGTrack | 52.08 | 41.10 | 66.04 | 57.57 | 58.36 | 71.13 | 87.98 | 90.54 | |
| DRTrack | 51.36 | 41.77 | 63.17 | 52.18 | 67.46 | 78.49 | 78.43 | 90.78 |
Qualitative Comparison across Methods
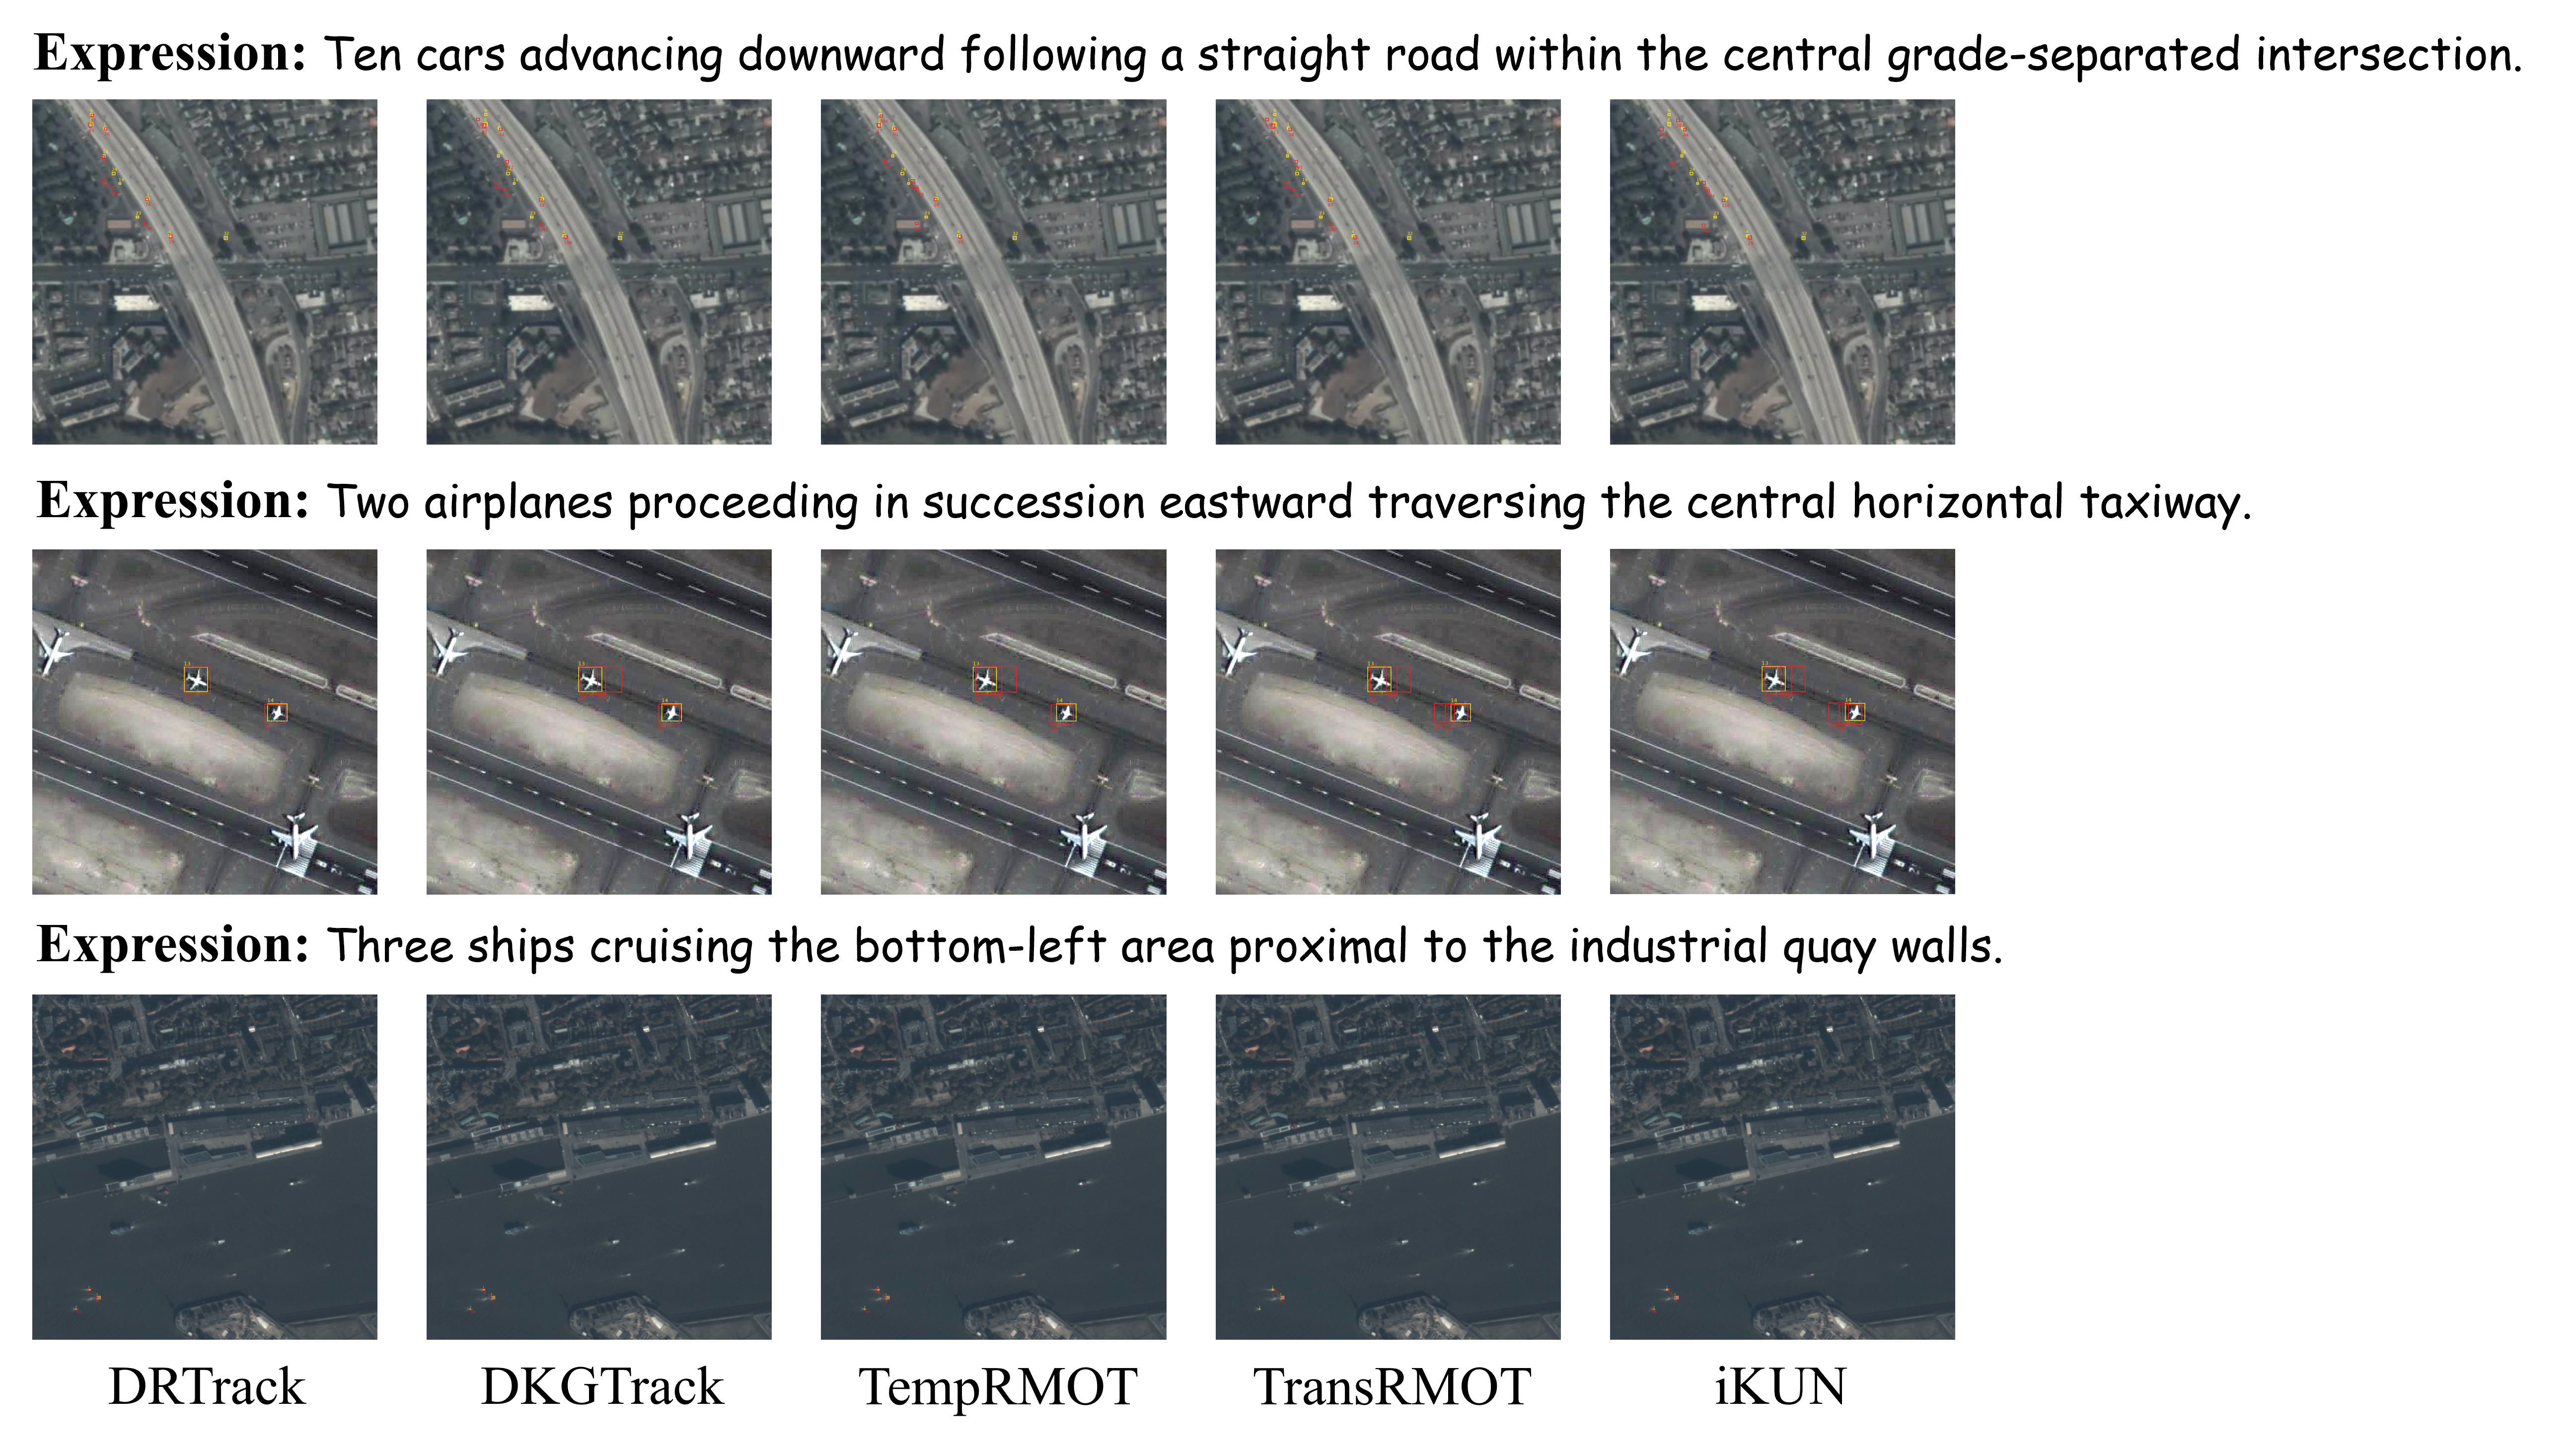
Figure 10. Qualitative visualization of different methods on SatRMOT. The comparison highlights how richer language grounding and stronger visual-linguistic refinement help DRTrack localize the referred tiny objects more consistently in dense satellite video scenes.
Implementation Details
During training, the text encoder remains fixed and only the rest of the network is updated. We optimize the model with AdamW, start from an initial learning rate of 1 × 10⁻⁴, and reduce it by a factor of 10 after the 40th epoch. For the objective design, the loss weights are set as αcls = 5, αbox = 2, αgiou = 2, and αref = 2. In the post-filtering stage, we keep target boxes with a confidence threshold of 0.3 and use a referring matching threshold of 0.4.
Qualitative Results on Cars
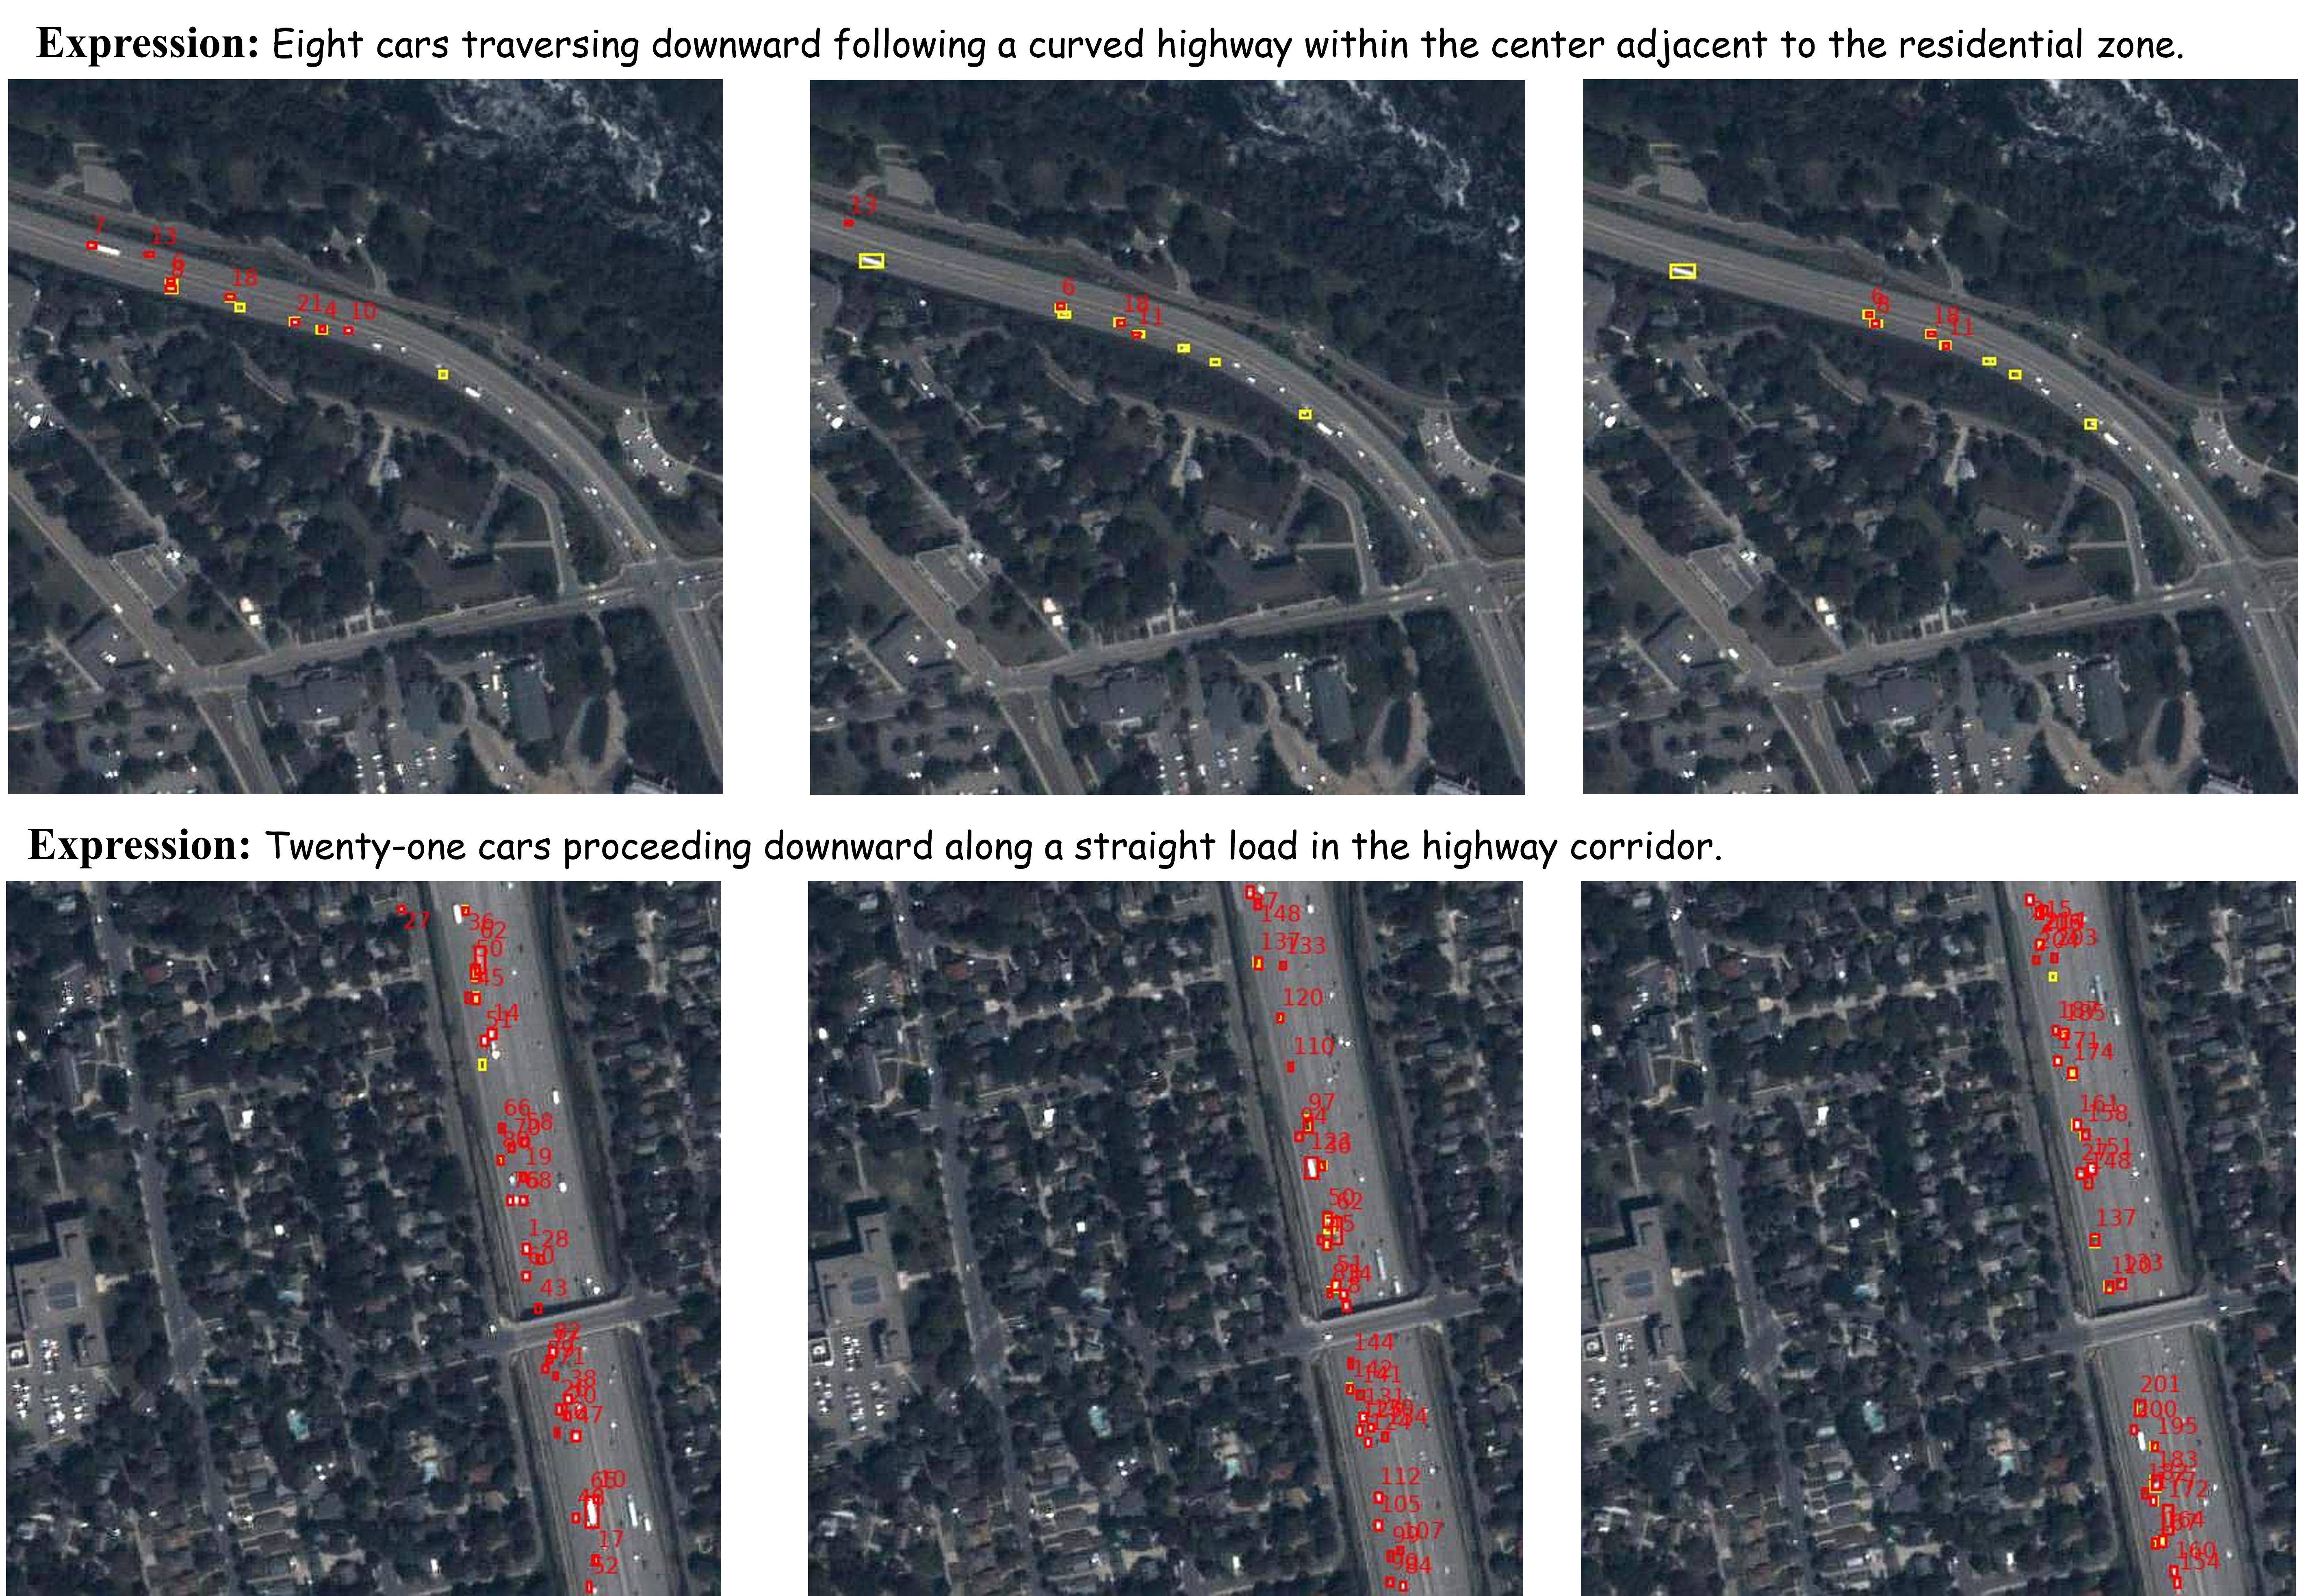
Figure 11. Qualitative visualization results for the car category. Groundtruth boxes are shown in yellow. Predicted boxes are drawn in red for cars.
Qualitative Results on Airplanes
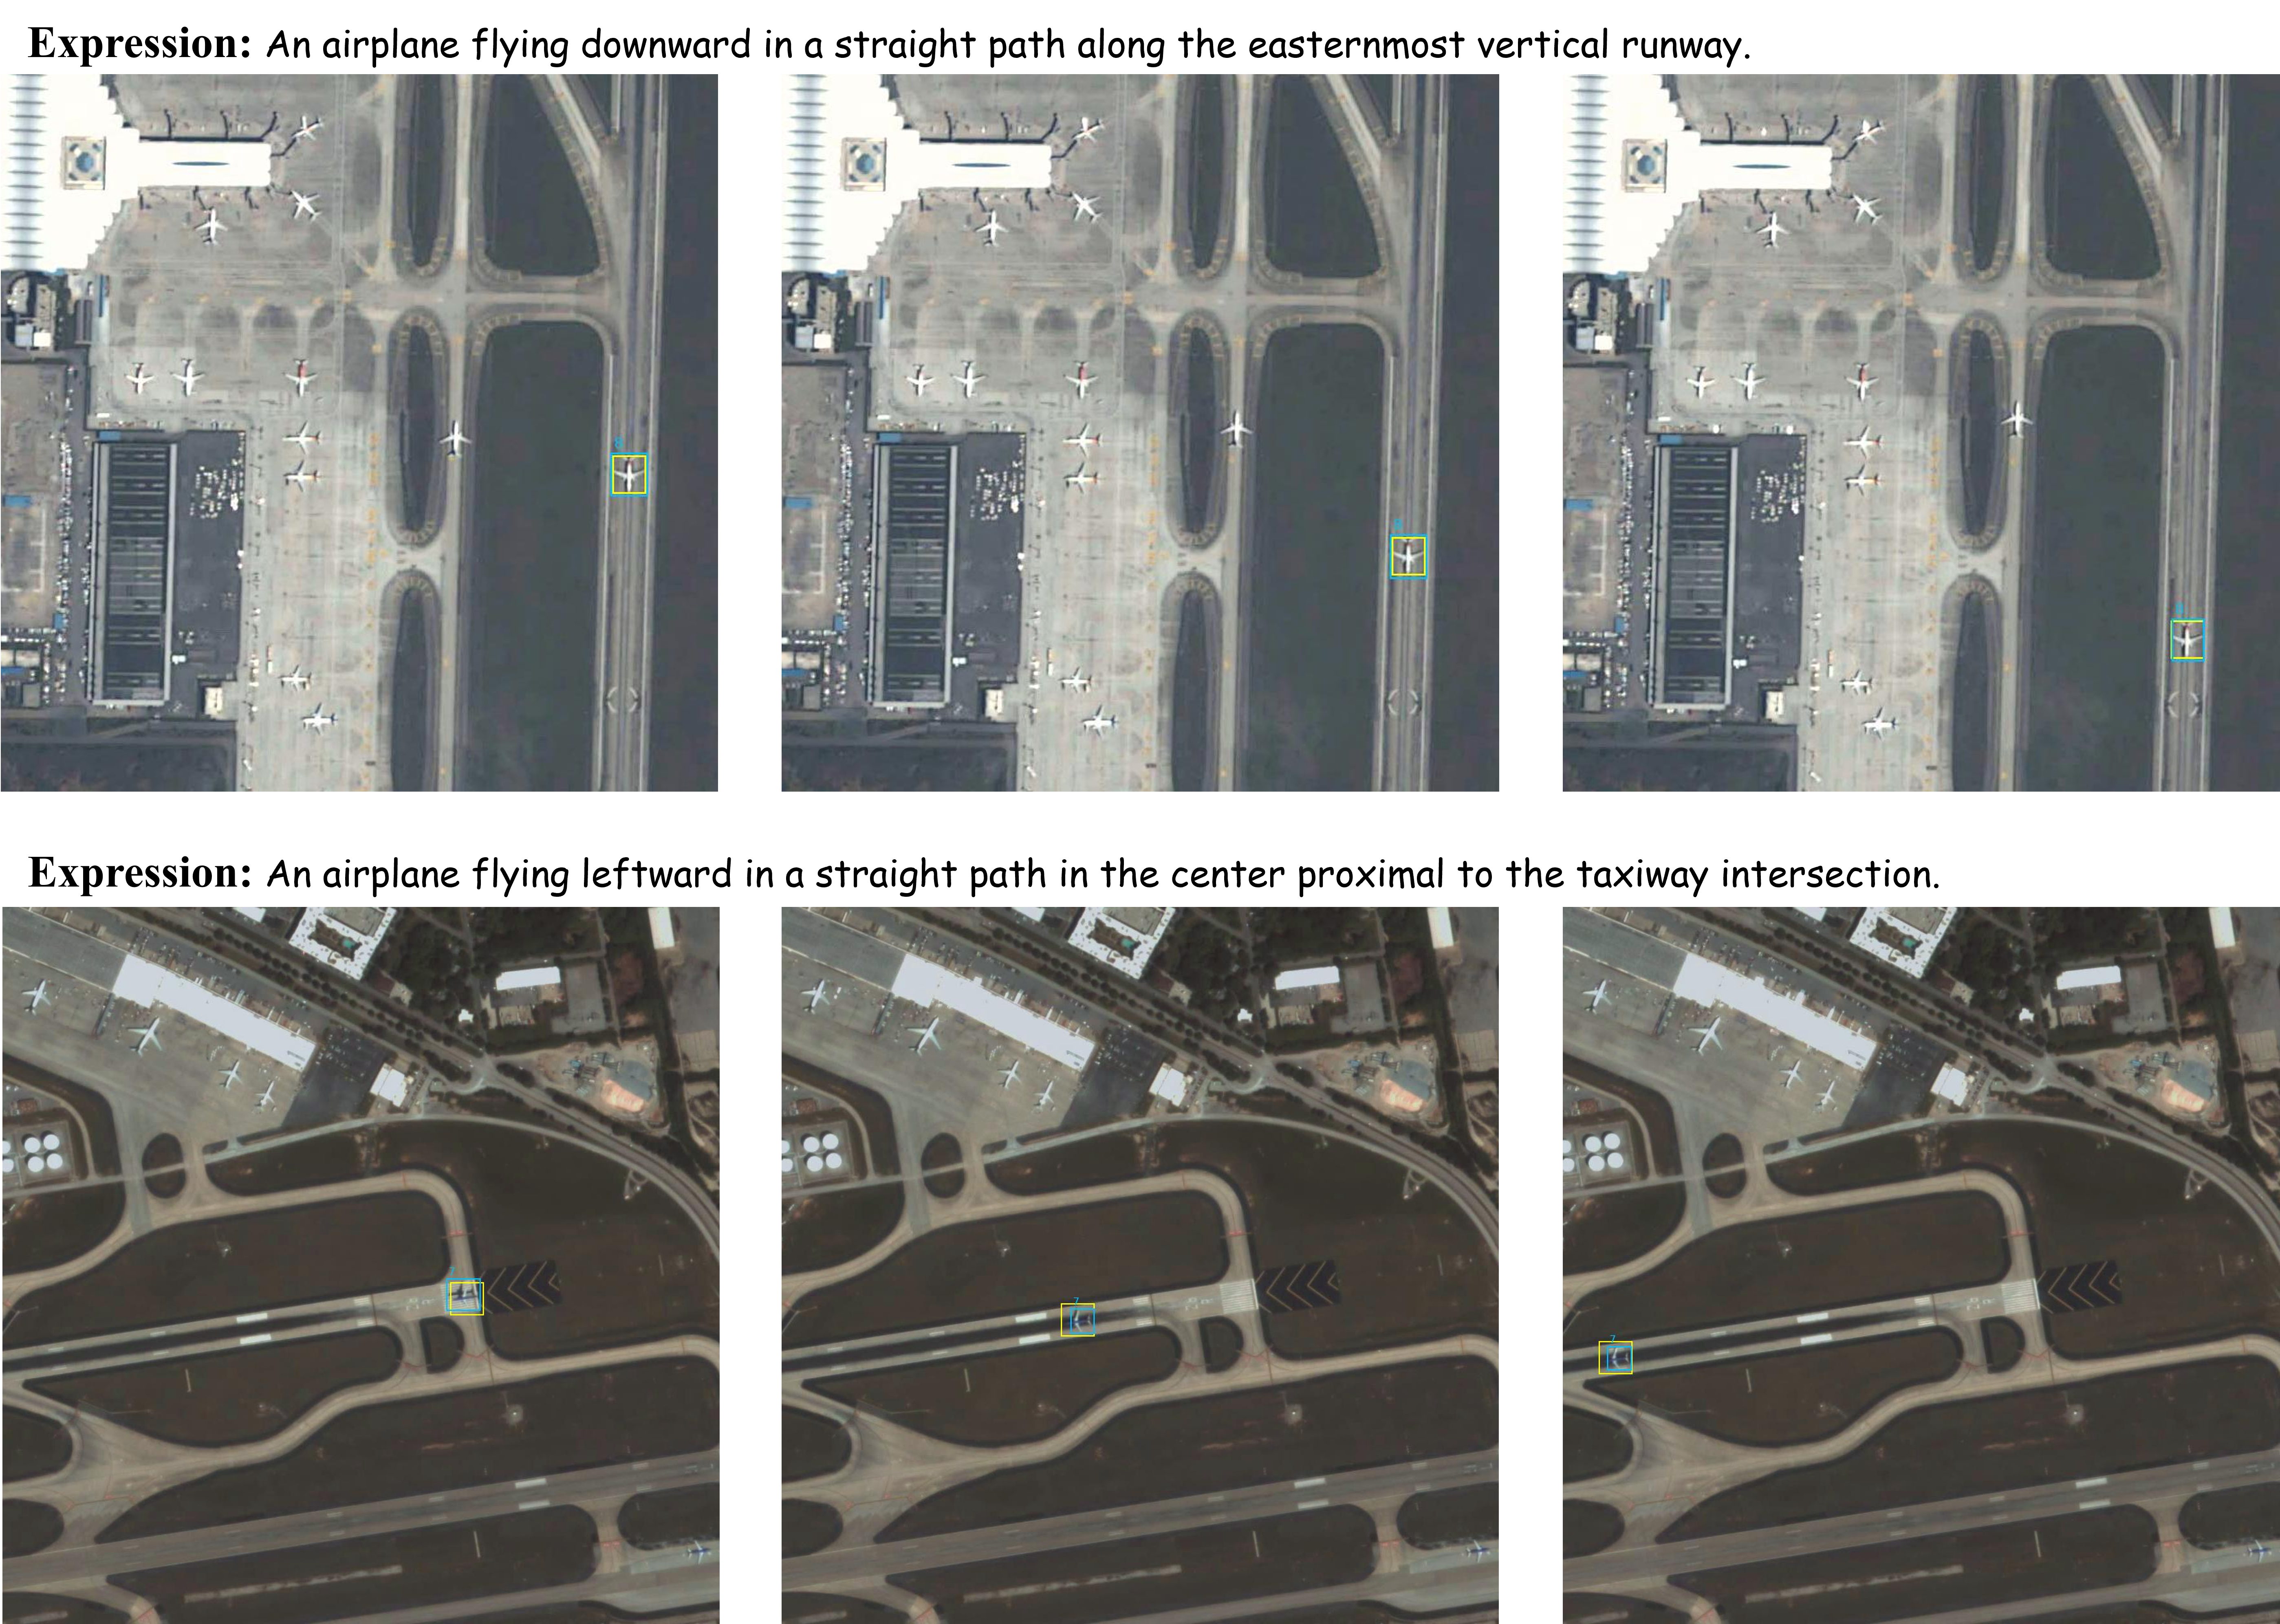
Figure 12. Qualitative visualization results for the airplane category. Groundtruth boxes are shown in yellow. Predicted boxes are drawn in blue for airplanes.
Qualitative Results on Ships
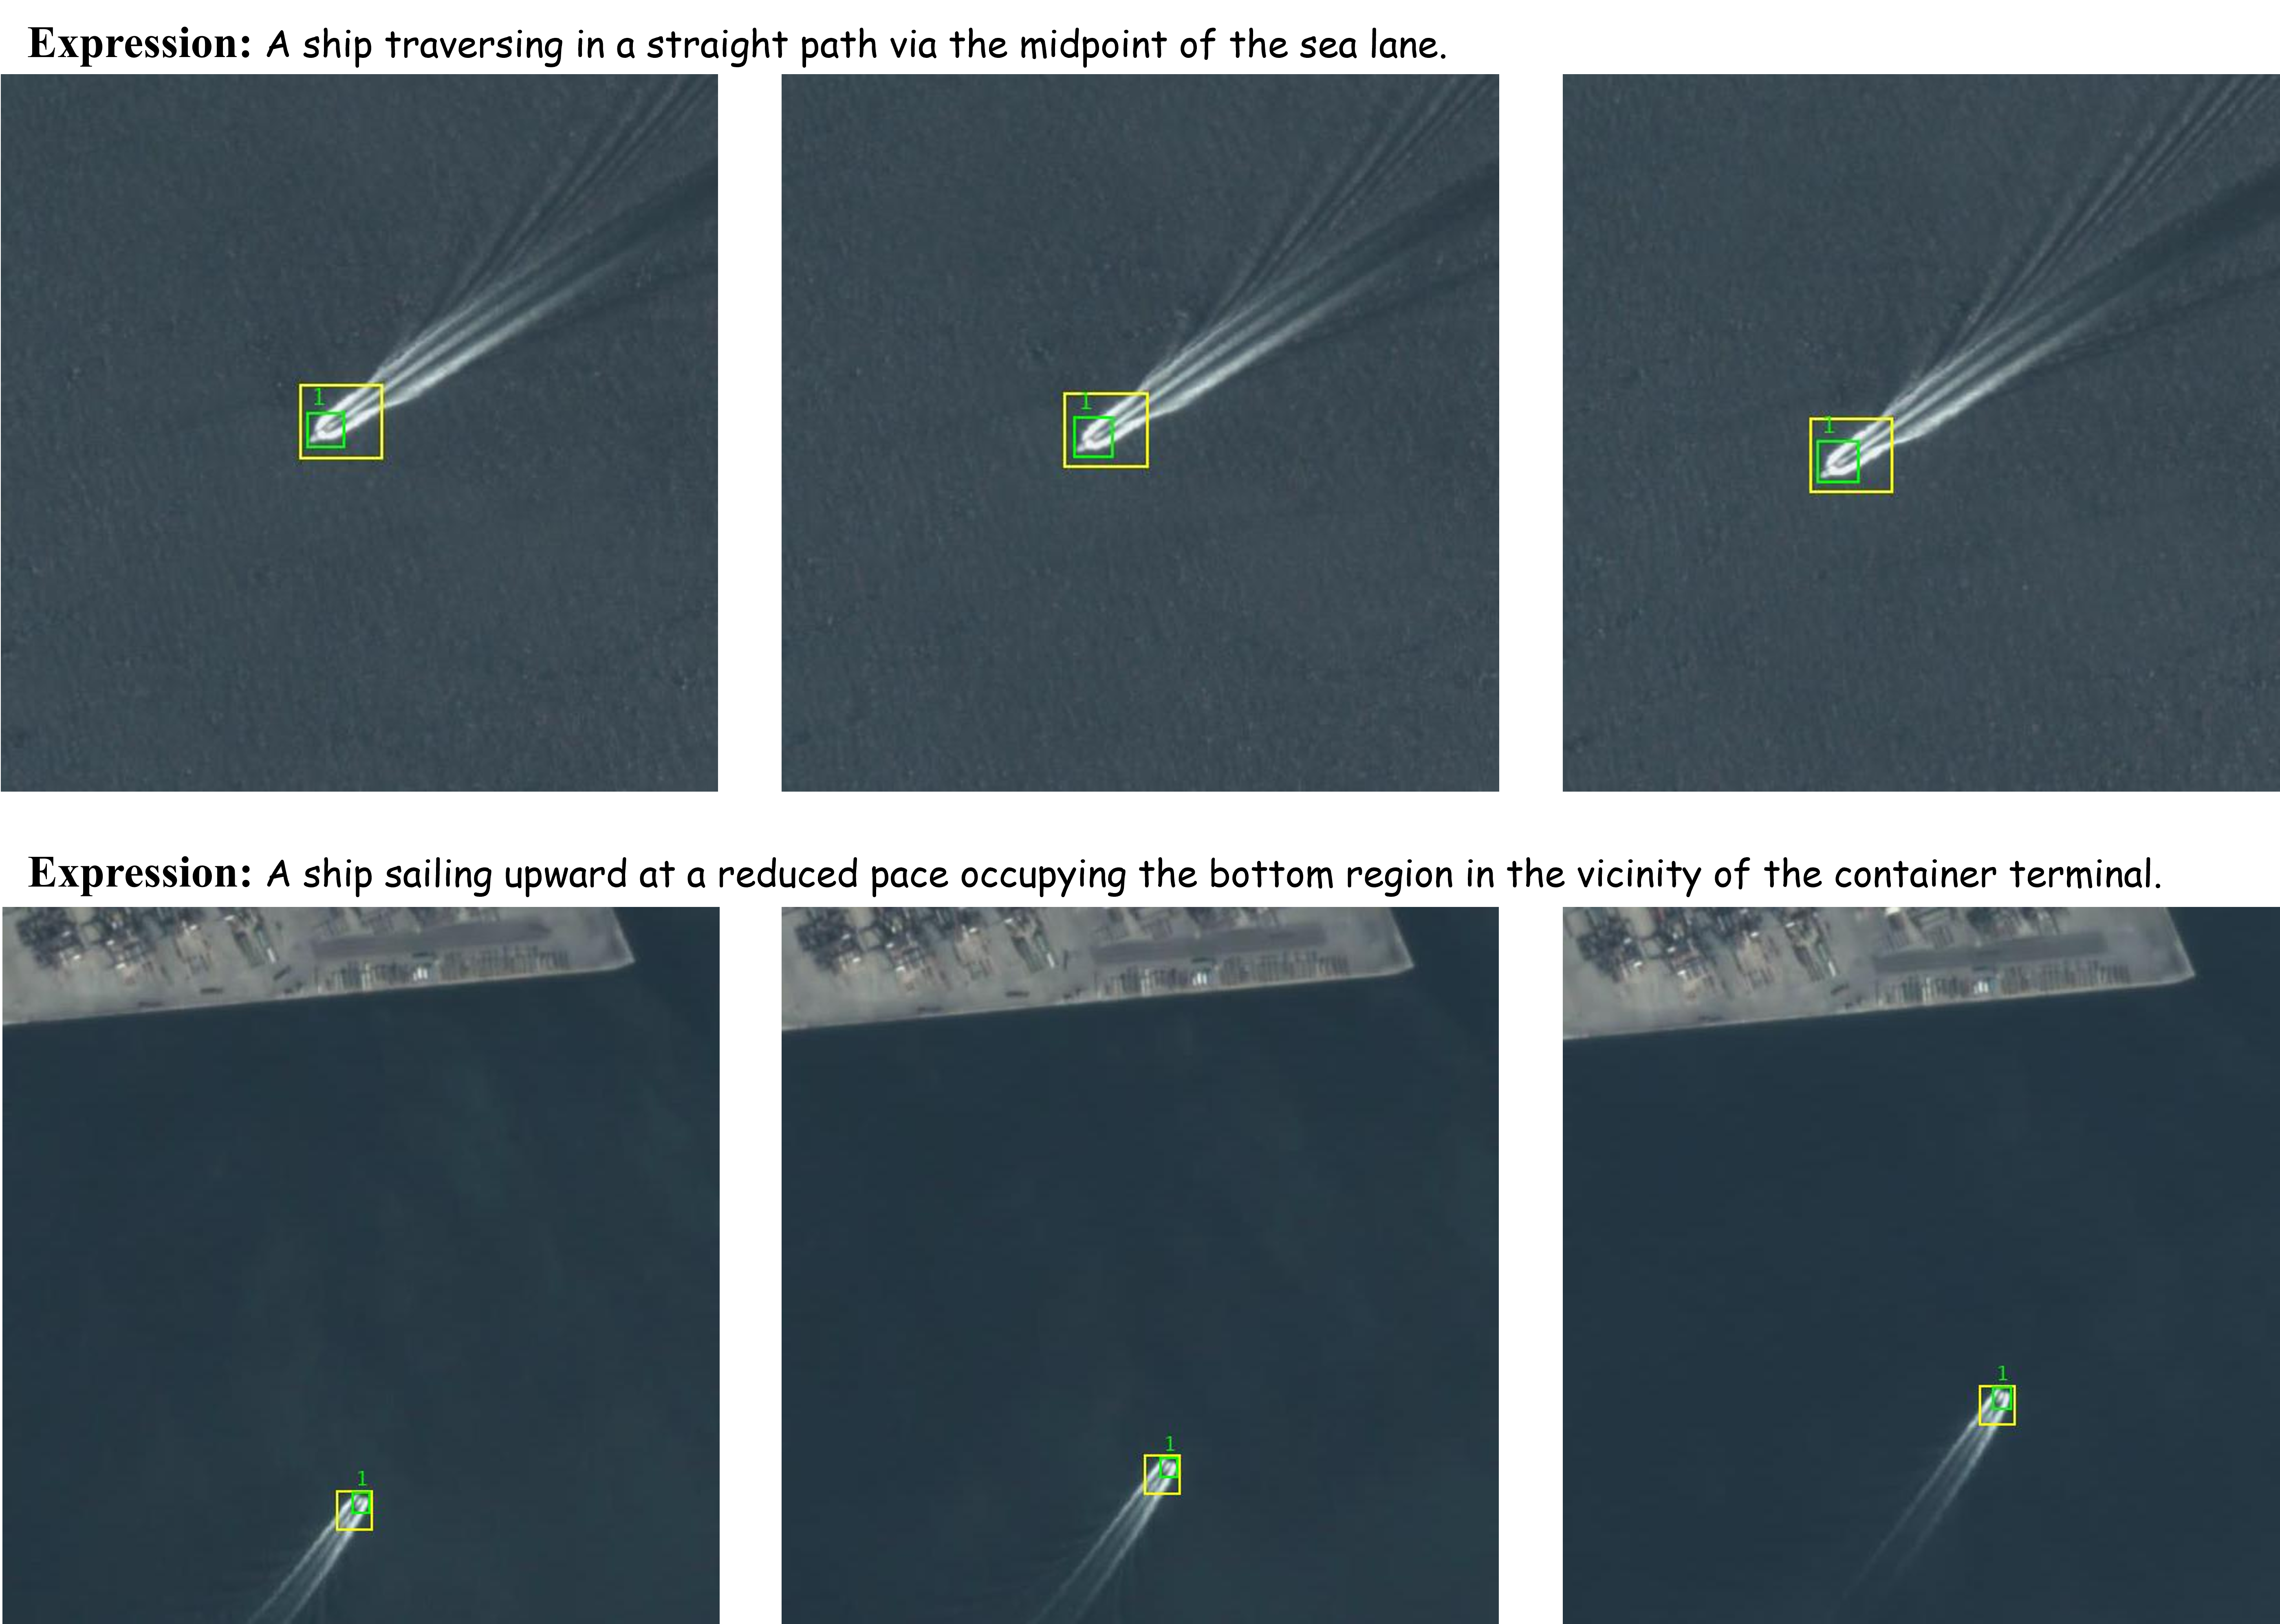
Figure 13. Qualitative visualization results for the ship category. Groundtruth boxes are shown in yellow. Predicted boxes are drawn in green for ships.
The SatRMOT dataset is released under the License CC BY-NC-ND 4.0 . This dataset is provided for academic research purposes only. Any use of the dataset should clearly acknowledge the original source, and neither modification nor redistribution is allowed unless prior permission has been obtained.